Multi-platform programming
Software Process Engineering
Giovanni Ciatto — giovanni.ciatto@unibo.it
Compiled on: 2026-11-06 — printable version
Outline
- Preliminaries: software platforms, API and runtimes, platform choice, technological silos
- Approaches: write once, build anywhere vs. write first, wrap elsewhere
- Write once, build anywhere with Kotlin: targets, project structure, build configuration,
expect/actual - Running example: a multi-platform CSV library, for the JVM and JS
- Calling Kotlin from other platforms: Kotlin–Java and Kotlin–JS mappings
- Multi-platform CI/CD: testing and releasing on several platforms
- Write first, wrap elsewhere with JPype: wrapping the JVM library into a Pythonic package
- Wrap-up: comparing the two approaches
Example code:
unibo-spe/multiplatform-example
Multi-platform programming
Preliminaries
What are software platforms?
-
Fuzzy concept
- often mentioned in courses / literature, yet not precisely defined
-
Insight:
The substratum upon which software applications run
What are software platforms?
Operating systems (?)
What are software platforms?
Operating systems + ???
-
Programming languages?
- not that simple
- e.g. Scala apps can call Java code
- not that simple
-
Runtimes
- i.e. the set of libraries and conventions backing programming languages
What are software platforms?
Definition attempt
Software platform $\stackrel{\Delta}{=}$ anything having an API enabling the writing of applications, and the runtime supporting the execution of those applications
- what are APIs and runtimes, then?
What are APIs and runtimes?
API $\equiv$ application programming interface(s) $\stackrel{\Delta}{=}$ a formal specification of the set of functionalities provided by a software (sub-)system for external usage, including their inputs, outputs, and environmental preconditions and effects
- client-server metaphor is implicit
Runtime [system/environment] $\approx$ the set of computational resources backing the execution of a software (sub-)system
- we say that “runtimes support API”
What are APIs and runtimes?
Examples of APIs
-
all possible public interfaces / classes / structures in an OOP module
- and their public/protected methods / fields / properties / constructors
- and their formal arguments, return types, throwable exceptions
- and their public/protected methods / fields / properties / constructors
-
all possible commands a CLI application accepts as input
- and their admissible sub-commands, options, and arguments
- and the corresponding outputs, exit values, and side effects
- and their admissible sub-commands, options, and arguments
-
all possible routes a Web service may accept HTTP requests on
- and their admissible HTTP methods
- and their admissible query / path / body / header parameters
- and the corresponding status codes, and response bodies
- and their admissible query / path / body / header parameters
- and their admissible HTTP methods
What are APIs and runtimes?
Examples of runtimes
-
any virtual machine or interpreter (JVM, CLR, CPython, V8)
- and their standard libraries
- and their type system and internal conventions
- e.g. primitive/reference types in the JVM, value/reference types in the CLR, global lock in CPython
-
any operating system (Win, Mac, Linux)
- and their system calls, daemons, package managers, default commands, etc.
- and their program memory, access control, file system models
-
any Web service
- and the protocols they leverage
- and their URL structuring model
- the data schema of their input/output objects
- the authentication / authorization mechanisms they support
Notable platforms
-
The Java Virtual Machine (JVM)
- supported languages: Java, Kotlin, Scala, Clojure, etc.
-
.NET’s [pronounced “dot NET”] Common Language Runtime (CLR), cross-platform since .NET Core
- supported languages: C#, VB.NET, F#, etc.
-
Python 3
- supported language: Python
-
NodeJS (V8), and alternative JS runtimes such as Deno and Bun
- supported languages: JavaScript, TypeScript (via type stripping or transpilation), etc.
-
Each browser may be considered as a platform per se
- supported languages: JavaScript, plus anything compiled to WebAssembly (Wasm)
-
Native code for each OS + CPU architecture (e.g. via LLVM), and mobile platforms (Android, iOS)
-
…
Practical features of platforms
-
standard libraries
- i.e. ready-made functionalities developers / users may exploit
-
predefined design decisions
- e.g. global interpreter lock in CPython, event loop in JavaScript, etc.
-
organizational, stylistic, technical conventions
- e.g. project structure, code linting, nomenclature, etc.
-
packaging conventions, import mechanisms, and software repositories
- e.g. classpath for the JVM, npm for JS, pip + PyPI for Python, etc.
-
user communities
- e.g. many Data scientists use Python, many Web developers use JVM / JS
Example: the JVM platform
Standard and community libraries: JVM
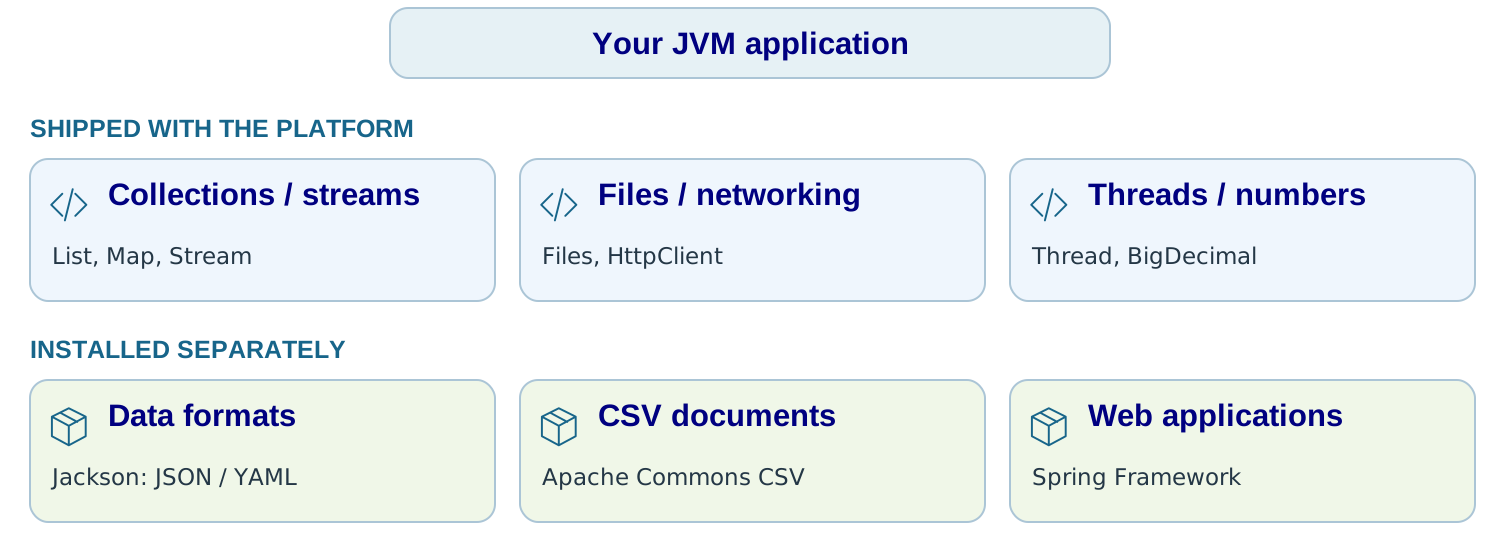
- JDK APIs are shared across JVM languages: Java, Kotlin, Scala, etc.
- Community libraries add domain-specific abstractions (e.g. Commons CSV), resolved by Maven / Gradle
Predefined design decisions: JVM
- Every class extends
Object- primitives are distinct; boxing wraps them
- Every object has a monitor
synchronizedinstance methods lock the receiver
- Java instance methods are virtual by default
toString()dispatches to the runtime class- Kotlin methods are
finalby default
Run the full example:
java -ea DesignDecisions.java
public class DesignDecisions {
    static class Counter {
        private int value;

        public synchronized void increment() {
            value++; // the receiver's monitor protects this update
        }

        @Override
        public String toString() {
            return "Counter(" + value + ")";
        }
    }

    public static void main(String[] args) {
        Counter counter = new Counter();
        counter.increment();
        Object object = counter; // every class extends Object
        System.out.println(object); // virtual call: Counter(1)
        int primitive = 1; // not an Object
        Object boxed = primitive; // autoboxed to Integer
Organizational, stylistic, technical conventions: JVM
Organization: Maven directory layout
project/
├── pom.xml (or build.gradle.kts)
└── src/
    ├── main/java/it/unibo/spe/
    │   └── CsvRow.java
    └── test/java/it/unibo/spe/
        └── CsvRowTest.java
- Style:
CsvRow,getValues,values - Technical protocols:
Iterableenables the enhancedforloop - Collections accept
Collection; variadicString...is aString[]
Full code, including a main and assertions
package it.unibo.spe;

import java.util.Collection;
import java.util.Iterator;
import java.util.List;

public class CsvRow implements Iterable<String> {
    private final List<String> values;

    public CsvRow(Collection<String> values) {
        this.values = List.copyOf(values);
    }

    public List<String> getValues() { // JavaBean getter
        return values;
    }

    @Override
    public Iterator<String> iterator() {
        return values.iterator();
    }

    public static void main(String... args) { // String[]
        var row = new CsvRow(List.of("Ada", "42"));
        for (String value : row) System.out.println(value);
        assert row.getValues().equals(List.of("Ada", "42"));
    }
}
Packaging, imports, repositories: JVM
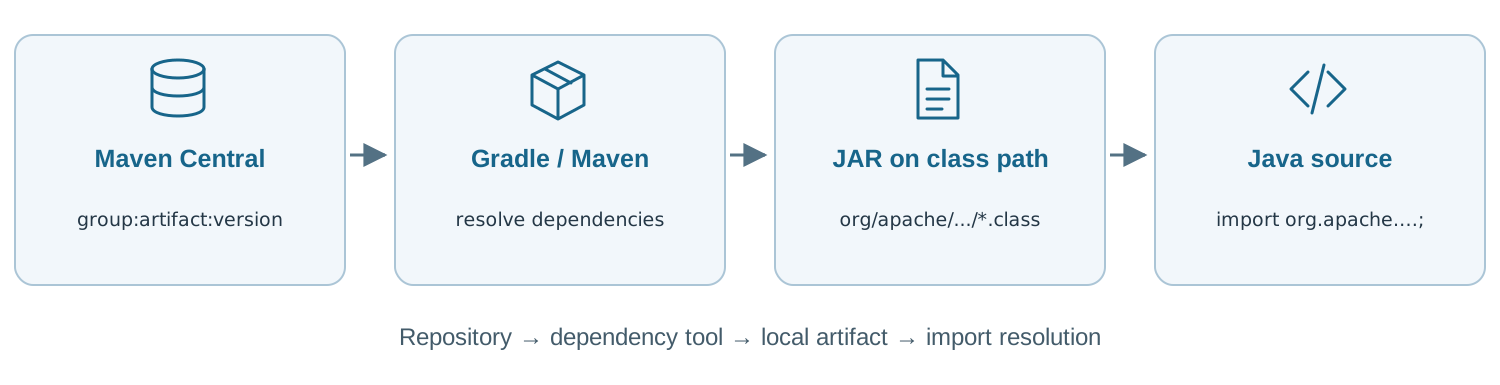
- Package → namespace, e.g.
org.apache.commons.csv - JAR → ZIP archive of compiled classes and resources
- Dependency coordinates →
org.apache.commons:commons-csv:1.14.1
- Import →
import org.apache.commons.csv.CSVFormat; - Class path → where the JVM finds classes (
java -cp ...) - Module path → also available for JPMS modules since Java 9
Resolve dependencies first; import classes in source code
User communities: JVM
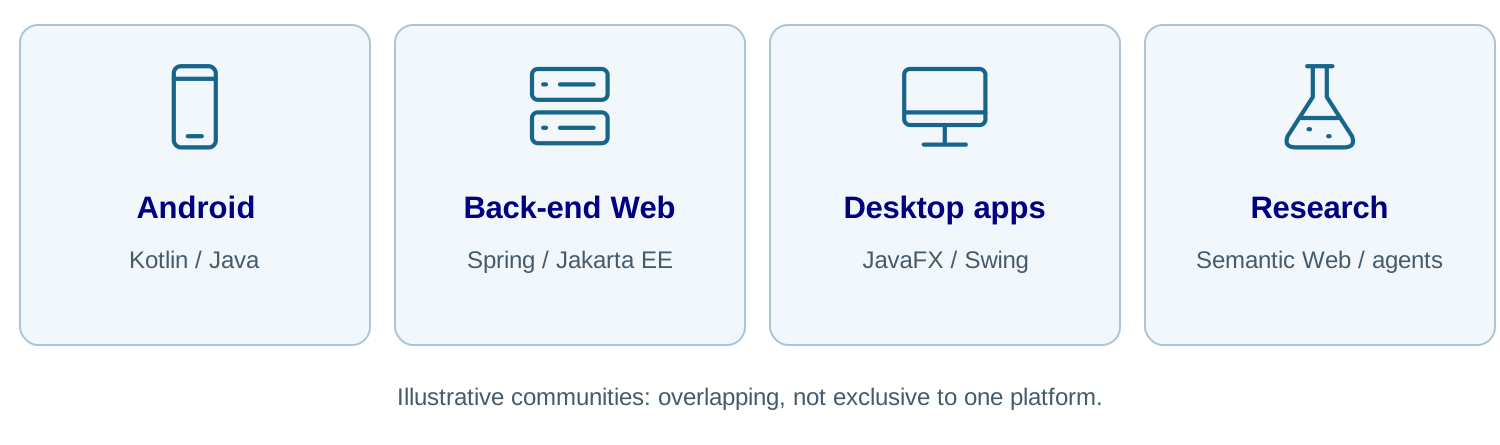
The same JVM library can reach several communities through their preferred JVM language
Example: the .NET platform
Standard and community libraries: .NET
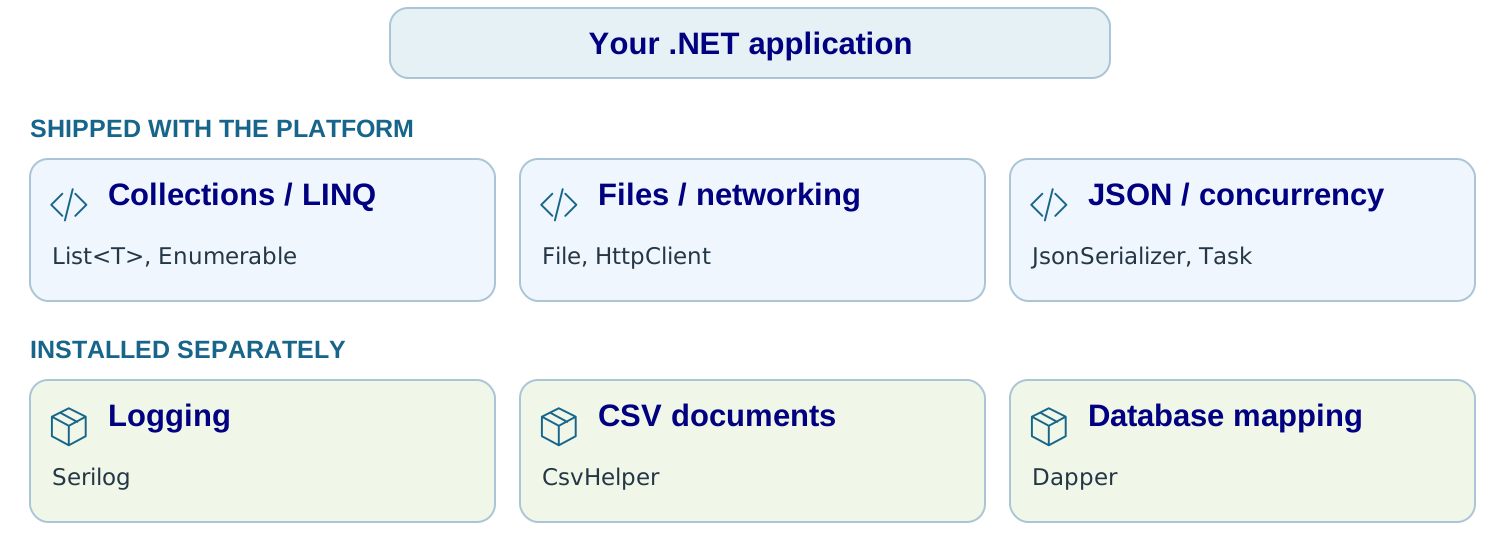
- The base class library provides common APIs for C#, F#, VB.NET, etc.
- Community packages add higher-level abstractions, distributed through NuGet
Predefined design decisions: .NET / C#
- Value types (
struct,int, etc.) vs. reference types (class)- assignment copies a value or a reference
- boxing wraps a copy of a value as an
object
- C# instance methods are non-virtual by default
- opt in with
virtual; specialize withoverride Object.ToString()is already virtual
- opt in with
- Properties expose accessors with field-like syntax:
counter.Value
Complete solution (.NET 10 SDK): from PlatformExamples/, run dotnet run --project CsvDemo
        Point first = new Point { X = 1 };
        Point copy = first; // struct: copy the value
        copy.X = 2;
        var counter = new Counter();
        var alias = counter; // class: copy the reference
        alias.Value = 2;
        object boxed = first; // box a copy of the struct
        Console.WriteLine($"{first.X}, {copy.X}"); // 1, 2
        Console.WriteLine(counter); // Counter(2)
public struct Point
{
    public int X { get; set; }
}
public class Counter
{
    public int Value { get; set; }
    public override string ToString() => $"Counter({Value})";
}
Organizational, stylistic, technical conventions: .NET
Organization: solution → projects → namespaces
PlatformExamples/
├── PlatformExamples.sln
└── CsvDemo/
    ├── CsvDemo.csproj
    ├── Program.cs
    ├── Point.cs
    ├── Counter.cs
    ├── Models/
    │   └── CsvRow.cs
    ├── bin/  (generated assemblies)
    └── obj/  (generated build files)
- Each project builds an assembly; directories reflect namespaces:
Models/→CsvDemo.Models - One type per file, named after it;
Program.Mainis the entry point - Naming:
CsvRow,Count,GetEnumerator; interfaces start withI - Protocols:
IEnumerable<T>enablesforeach;paramsaccepts variadic arguments
using System.Collections;
using System.Collections.Generic;

namespace CsvDemo.Models;

public class CsvRow : IEnumerable<string>
{
    private readonly string[] _values;

    public CsvRow(params string[] values) // variadic arguments
    {
        _values = (string[])values.Clone();
    }

    public int Count => _values.Length; // property, not GetCount()

    public IEnumerator<string> GetEnumerator() =>
        ((IEnumerable<string>)_values).GetEnumerator();

    IEnumerator IEnumerable.GetEnumerator() => GetEnumerator();
}
Packaging, imports, repositories: .NET
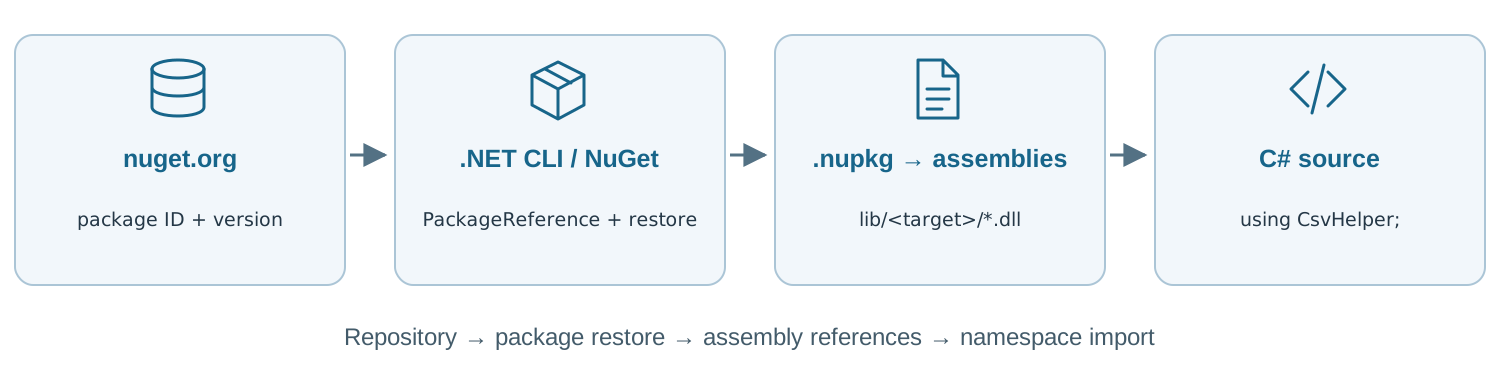
- NuGet package (
.nupkg) → ZIP with assemblies, metadata and other assets - Assembly (
.dll) → compiled types and metadata, targeting a framework - Repository: nuget.org, or a private package feed
- Dependency:
dotnet add package CsvHelperrecords a reference in.csprojand restores it - Namespace:
using CsvHelper;allows the short nameCsvReader usingneither downloads a package nor loads an assembly; namespaces and assemblies are distinct
NuGet resolves packages; assembly references make types available to the compiler
User communities: .NET / C#
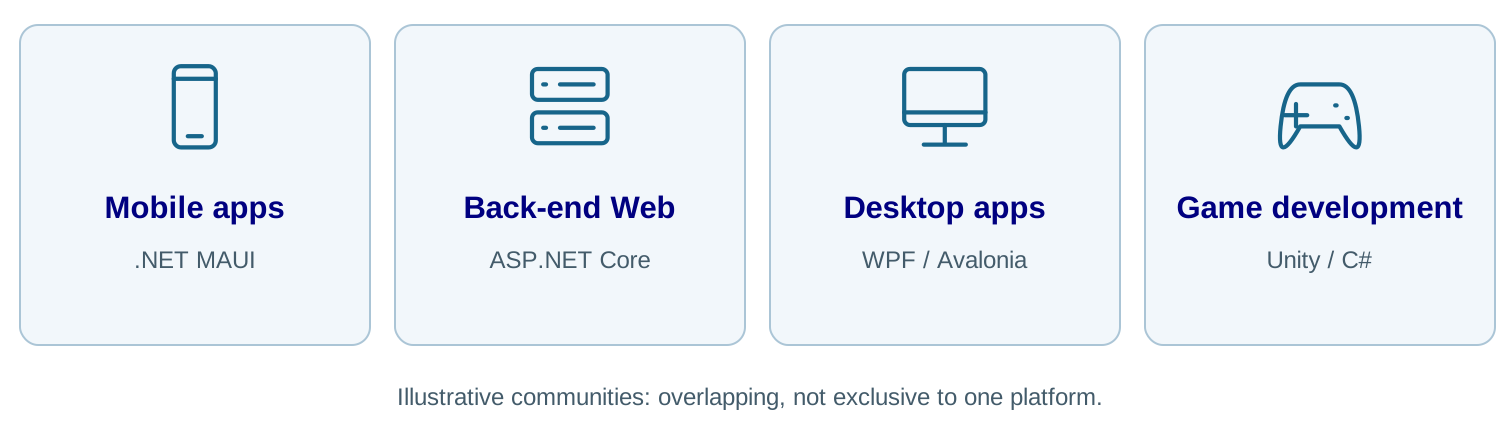
Frameworks have their own target platforms: e.g. WPF is Windows-only; Unity uses its own runtime tooling
Example: the Python platform
Standard and community libraries: Python
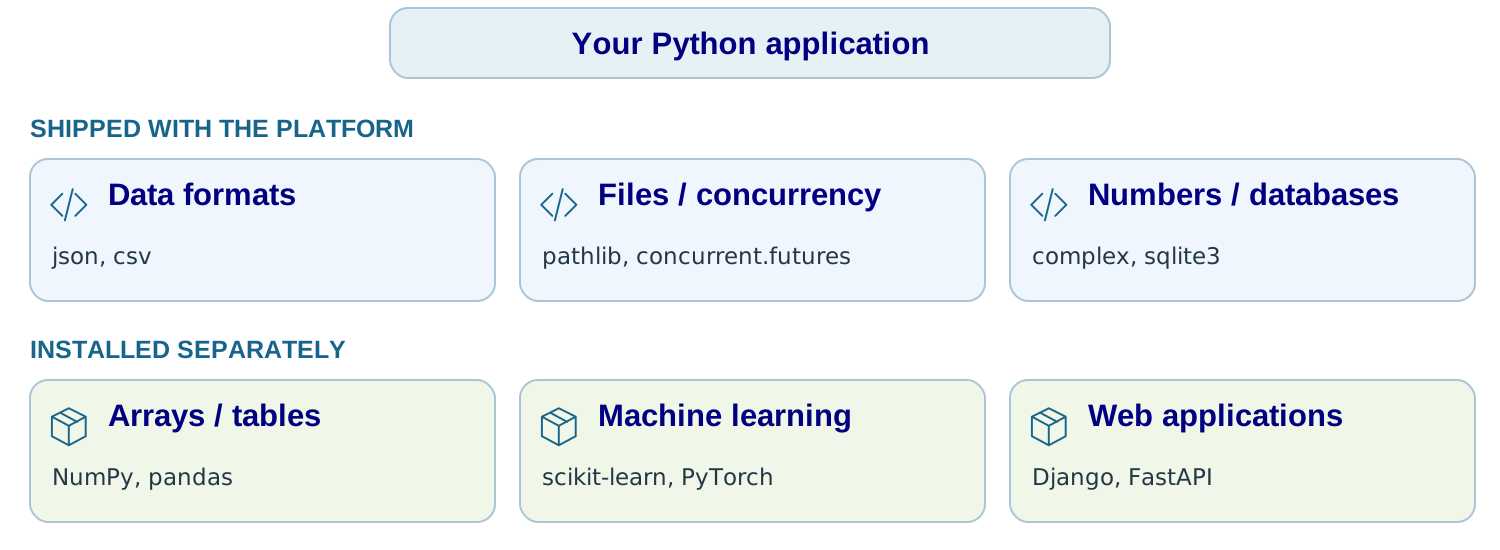
- The standard library already covers CSV / JSON, complex numbers, etc.
- Community packages add arrays, tables, ML models and Web frameworks
Predefined design decisions: Python
- Everything is an object, including numbers
- Magic methods connect objects to language features
str(row)→row.__str__()len(row)→row.__len__()
- No signature-based method overloading
- a later
defwith the same name replaces the earlier binding
- a later
- Default CPython builds have a GIL
- optional free-threaded builds exist since Python 3.13
Run the full example:
python3 design_decisions.py
class Row:
    def __init__(self, *values):
        self.values = values

    def __str__(self):
        return ",".join(self.values)

    def __len__(self):
        return len(self.values)


row = Row("Ada", "42")
print(str(row))  # Ada,42: dispatches to __str__
print(len(row))  # 2: dispatches to __len__
print(isinstance(42, object))  # True, even for integers
Organizational, stylistic, technical conventions: Python
Organization: src layout (flat layout is also common)
project/
├── pyproject.toml
├── src/csv_demo/
│   ├── __init__.py
│   └── csv_row.py
└── tests/
    └── test_csv_row.py
- Style: PEP 8,
CsvRow,join_values, four spaces - Duck typing: same function accepts our object or a built-in list
*values→ tuple;**metadata→ dictionary
Full code, including assertions
class CsvRow:  # PascalCase type name
    def __init__(self, *values, **metadata):
        self.values = values       # tuple
        self.metadata = metadata   # dict

    def __iter__(self):
        return iter(self.values)


def join_values(row):  # snake_case; duck typing
    return ",".join(row)  # any iterable of strings


row = CsvRow("Ada", "42", source="demo")
print(join_values(row))  # Ada,42
print(join_values(["Ada", "42"]))  # same protocol
Packaging, imports, repositories: Python
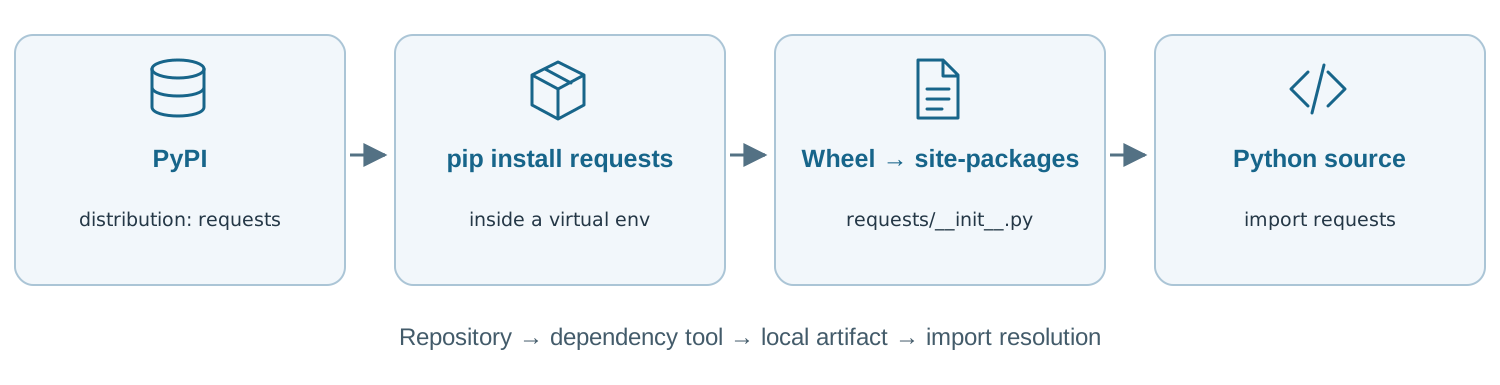
- Module →
.pyfile; regular package → directory with__init__.py - Wheel (
.whl) → installable ZIP (sources, optional native extensions, metadata) - Source distribution (
.tar.gz) → must first be built
- pip installs distributions from PyPI into an environment
importsearchessys.path, includingsite-packages- Distribution and import names can differ:
pip install scikit-learn→import sklearn
pip installs a distribution; import loads a module
User communities: Python
Scientific libraries reach users who expect Python objects and protocols, even when implemented in C / C++
Example: the NodeJS platform
Standard and community libraries: NodeJS
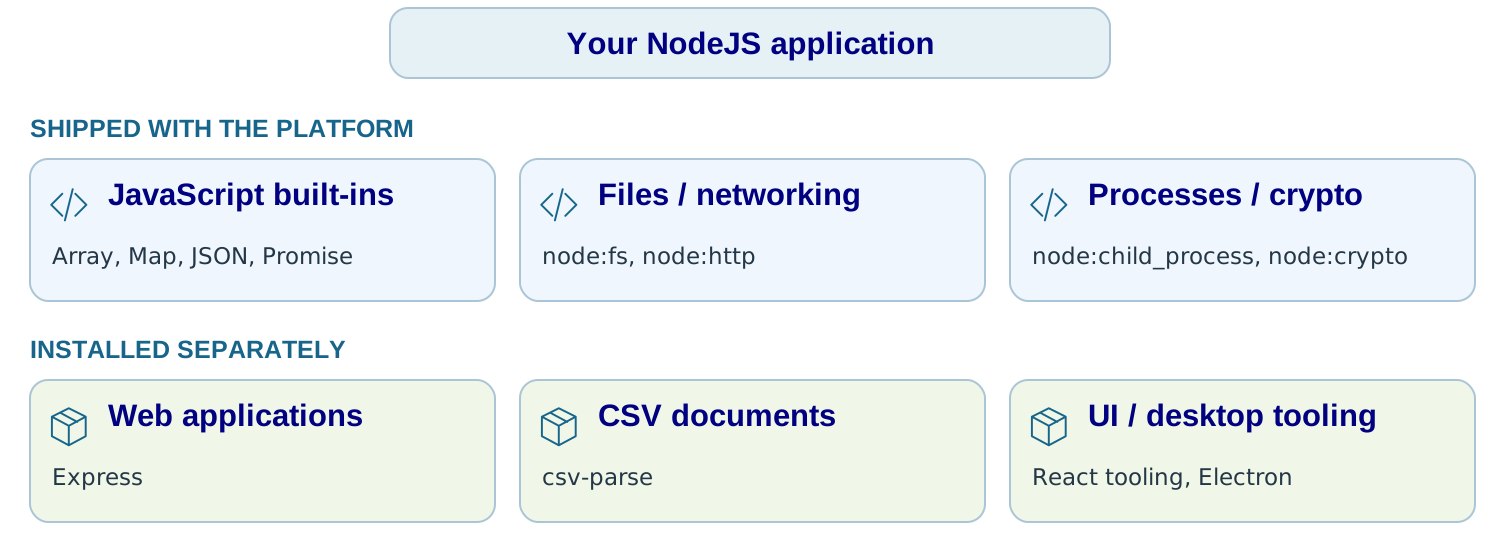
- JavaScript built-ins + Node APIs form the platform’s standard facilities
- Community packages add higher-level abstractions; browser DOM APIs are not part of Node
Predefined design decisions: NodeJS
- Prototype-based object orientation
rowinheritstoStringfrom its prototype
- JavaScript callbacks run on the event loop
- CPU-heavy work blocks other callbacks
- worker threads / processes enable parallelism
- Promises and
async/awaitawaitsuspends this async function- the caller continues before it resumes
Run the full example:
node design-decisions.mjs
const rowPrototype = {
  toString() { return this.values.join(','); }
};
const row = Object.create(rowPrototype);
row.values = ['Ada', '42'];
console.log(row.toString()); // inherited: Ada,42

const order = [];
async function readRow() {
  order.push('start');
  await Promise.resolve(row); // continuation runs later
  order.push('resumed');
}
const pending = readRow();
order.push('caller'); // await did not block the caller
await pending;
console.log(order); // ['start', 'caller', 'resumed']
Organizational, stylistic, technical conventions: NodeJS
Organization: one possible layout
project/
├── package.json
├── src/
│   └── csv-row.mjs
└── test/
    └── csv-row.test.mjs
- No mandatory source-directory layout
- Style:
CsvRow,joinValues; teams choose a linter / formatter - Duck typing and the iterable protocol (
Symbol.iterator) - Rest parameters → arrays;
.mjsexplicitly selects ES modules
Full code, including assertions
export class CsvRow { // PascalCase type name
  constructor(...values) { // rest arguments: Array
    this.values = values;
  }

  [Symbol.iterator]() { // iterable protocol
    return this.values[Symbol.iterator]();
  }
}

function joinValues(row) { // camelCase; duck typing
  return [...row].join(','); // any iterable
}

const row = new CsvRow('Ada', '42');
console.log(joinValues(row)); // Ada,42
console.log(joinValues(['Ada', '42'])); // same protocol
Packaging, imports, repositories: NodeJS
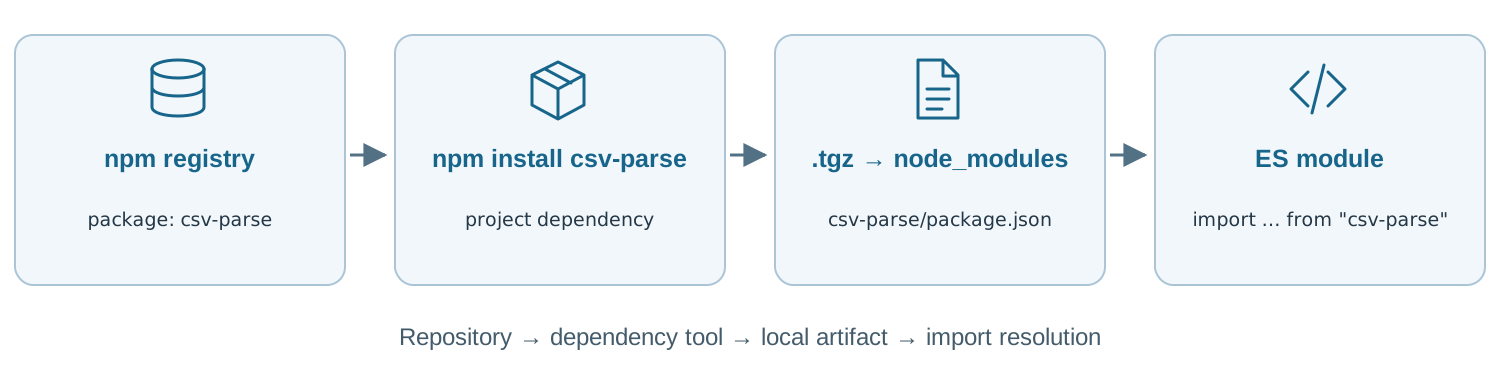
- Package →
package.json+ sources / assets, distributed as.tgz - npm registry → repository;
npm→ dependency tool (alsoyarn,pnpm) npm install csv-parse→ local dependency innode_modules
- ES modules:
import { parse } from 'csv-parse'; - CommonJS:
const { parse } = require('csv-parse'); - Resolution: package entry points via
exports/main; relative ESM imports include the extension, e.g../csv-row.mjs
npm installs packages;
import/requireloads their exported modules
User communities: NodeJS
Front-end code runs in the browser; Node often runs its build tools or server-side rendering
Platforms from software developers’ perspective
The choice of a platform impacts developers during:
-
the design phase
-
the implementation phase
-
the testing phase
-
the release phase
How the platform affects the design phase
- One may choose the platform which minimizes the abstraction gap w.r.t. the problem at hand
Abstraction gap $\approx$ the space between the problem and the pre-existing functionalities offered by a platform. Intuitively, the bigger the space, the more effort is required to build the solution

How the platform affects the implementation phase
-
Developers write solutions by leveraging the API of the platform
-
… as well as the API of any third-party library available for that platform

How the platform affects the testing phase
-
Test suites are a “project in the project”
- so remarks are similar to the implementation phase
-
One may test the system against as many versions as possible of the underlying platforms
-
One may test the system against as many OSs as possible
- virtual platforms may behave differently depending on the OS
-
Both are typically automated via CI build matrices (cf. CI lecture)
How the platform affects the release phase
Release $\approx$ publishing some packaged software system onto a repository, hence enabling its import and exploitation
-
Packaging systems are platform-specific…
-
Repositories are platform-specific…
-
… release is therefore platform specific (cf. version selection and CI)
Platform choice for a new SW project
-
Choice is commonly driven by design / technical decisions
- which platform would ease developers’ work the most?
-
However, choosing the platform is a business decision as well
- platforms have user communities
- SW projects benefit from wide(r) user communities
-
Business decision: which user communities to target?
- what are the most relevant platforms for those communities?
-
Coherence is key for success in platform selection
- coherently choose the target community w.r.t. the SW goal
- coherently choose the platform w.r.t. target community
What about research-oriented software? (pt. 1)
Researchers may act as software developers
-
to elaborate data
-
to create in-silico experiments
-
to study software systems
-
to create software tools improving their research
-
to create software tools for the community
- this is how many FOSS tools have been created
What about research-oriented software? (pt. 2)
Research institutions are not software houses
-
Personnel can only dedicate a fraction of their time to development
-
Most software artifacts are disposable (data elaboration, in-silico experiments, personal tools)
-
Development efforts are discontinuous
-
Development teams are small
-
Software is commonly a means, not an objective
-
Commitment to software development is:
- commonly on the individual
- sometimes on the project
- rarely on the institution
What about research-oriented software? (pt. 3)
Research-oriented software development should maximise audience and impact, while minimising development and maintenance effort
-
Science requires reproducibility
- a wide(r) user base is a facilitator for reproducibility
-
The wider the community, the wider the impact of community-driven research software
- more potential citations
-
Minimising effort can be done by improving efficiency
- by means of software engineering
General benefits of coherence (in general, and for researchers)
Choosing the right community / platform is strategic, especially for research-oriented software
-
The abstraction gap is likely lower
- less development effort
-
More third party libraries are likely available
- less development effort
-
The potential audience is wider
- more value, more impact, more reproducibility
-
Easier to find support / help in case of issues
- potentially, less development effort
-
More likely that third-party issues are fixed in a timely manner
- potentially, less development effort
About technological silos
Silos (in IT) are software components / systems / ecosystems having poor external interoperability (i.e. software from silo A hardly interoperates with software from silo B)
-
Platforms are (pretty wide) software silos
- making software from any two platforms interoperate is non-trivial
- making software from the same platform interoperate is easier
-
Examples:
- intra-platform: Kotlin program calling Java library
- inter-platform: Python program calling a JVM library (e.g. via JPype, see later)
Open research communities vs. technological silos
-
Research communities in CS / AI may overlap with platform (or language) communities:
- e.g. neural networks researchers $\rightarrow$ Python
- e.g. data science $\rightarrow$ Python | R
- e.g. symbolic AI $\rightarrow$ JVM | Prolog
- e.g. multi-agent systems $\rightarrow$ JVM
- e.g. Semantic Web $\rightarrow$ JVM | Python
-
What about inter-community research efforts?
- they may need interoperability among different silos
- without which, research is slowed down
Multi-platform programming is an enabler for inter-community research
The need for multi-platform programming
-
Ideal goal:
let the same software tool run on multiple platforms
-
More reasonable goal:
create multiple artifacts, one for each supported platform, sharing the same design and functioning
-
Practical goal:
design and write the software once, then port it to several platforms
Approaches for multi-platform programming
-
Write once, build anywhere
- software is developed using some sort of “super-language”
- code from the “super-language” is automatically compiled for all platforms
- e.g. Kotlin Multiplatform, Haxe, Scala.js + Scala Native
- not to be confused with Java’s “write once, run anywhere”, where one artifact runs on one (virtual) platform, available on many OSs
-
Write first, wrap elsewhere
- software is developed for some principal platform
- implementations for all other platforms are wrappers of the first one
Write once, build anywhere (concept)

Write once, build anywhere (explanation)
-
Assumptions:
- one “super-language” exists, having:
- a code-generator targeting multiple platforms
- e.g. compiler, transpiler, etc.
- the same standard library implemented for all those platforms
- a code-generator targeting multiple platforms
- one “super-language” exists, having:
-
Workflow:
- Design, implement, and test most of the project via the super-language
- this is the platform-agnostic (a.k.a. “common”) part of the project
- Complete, refine, or optimise platform-specific aspects via
- platform-specific code
- platform-specific third-party libraries
- Build platform-specific artifacts, following platform-specific rules
- Upload platform-specific artifacts on platform-specific repositories
- Design, implement, and test most of the project via the super-language
Write once, build anywhere (analysis)
Let N be the number of supported platforms
-
Platform-agnostic functionalities require effort which is independent of
N -
Platform-specific functionalities require effort proportional to
N -
Better to minimise platform-specific code
- by maximising common code
- this is true both for main code and for test code
-
Relevant questions:
- what to realise as common code? what as platform-specific code?
- how to set the boundary of the common (resp. platform-specific) code?
Takeaway
The abstraction gap of the common code is at least as wide as the one of the platform having the widest abstraction gap (the common std-lib is roughly the intersection of what all platforms offer)

Write once, build anywhere (strategy)
Whenever a new functionality needs to be developed:
-
Try to realise it with common std-lib only
-
If not possible, try to maximise the portion of platform-agnostic code
- make it possible to plug platform-specific aspects
-
For each functionality which cannot be realised as purely platform-agnostic:
- design a platform-agnostic interface
- implement the interface
Ntimes, one per target platform
Write first, wrap elsewhere (concept)

Write first, wrap elsewhere (explanation)
-
Assumptions:
- one “main” platform exists such that
- code from the “main” platform can be called from other target platforms
- the software has been designed in a platform-agnostic way
- one “main” platform exists such that
-
Workflow:
-
Fully implement, test, and deploy the software for the main platform
-
For all other platforms:
- re-design and re-write platform-specific API code
- implement platform-specific API by calling the main platform’s code
- re-write tests for API code
- build platform-specific packages, wrapping the main platform’s package and runtime
-
Upload platform-specific artifacts on platform-specific repositories
-
Write first, wrap elsewhere (analysis)
Let N be the number of supported platforms
-
Clear separation of API code from implementation code is quintessential
-
The effort required for writing API code is virtually the same on all platforms
-
Global effort is still linear in
N, but with a much smaller constant- implementing API and wrapper code is a manual task
- still less effort than implementing the same design
Ntimes
-
The
i-th platform’s wrapper code will only call the main platform’s API code -
Relevant questions:
- how to deal with platform-specific aspects?
- how to create platform-agnostic design?
Multi-platform programming
Write once, build anywhere
Write once, build anywhere with Kotlin
-
JetBrains-made modern programming language
- focused on “practical use” (whatever that means)
-
Gaining momentum since Google adopted it as the official Android language (2017)
- Android development has been Kotlin-first since 2019
-
Clearly inspired by a mixture of Java, C#, Scala, and Groovy
- standard library clearly inspired by Java’s
-
Born in industry, for the industry
- initially considered a better Java
- focused on getting productive quickly and reducing programming errors
-
Acts as the “super language” supporting the “write once, build anywhere” approach
- Kotlin compilers are available for several platforms
- standard library implemented for those platforms
Kotlin: supported platforms (a.k.a. targets)
Reference: Kotlin Multiplatform DSL reference
-
JVM
- first and best supported platform
- the JDK to compile against should be selected explicitly, e.g.
kotlin { jvmToolchain(17) }
-
JavaScript (JS)
- requires choosing among Browser support, Node support or both
- the two sub-targets have different runtimes
-
WebAssembly (Wasm)
wasmJs(browsers, Node) andwasmWasi(WASI runtimes)
-
Android
- Android libraries and apps, via the Android Gradle plugin
-
Native
- supporting native may imply dealing with 3+ targets (OS $\times$ CPU architecture)
- any host can compile libraries (
.klibs) for any target, but final binaries for Apple targets require macOS
Kotlin: supported platforms, Native sub-targets
Reference: Kotlin/Native target support
-
Targets come in tiers, i.e. levels of testing on JetBrains’ CI:
- Tier 1 (compiled and run on CI):
macosArm64,iosArm64,iosSimulatorArm64 - Tier 2 (compiled on CI): e.g.
linuxX64,linuxArm64,watchosArm64,tvosArm64 - Tier 3 (not guaranteed to be tested): e.g.
mingwX64(Windows),androidNative* - some targets are deprecated (e.g.
macosX64since Kotlin 2.3.20)
- Tier 1 (compiled and run on CI):
-
Windows via MinGW, Linux
- must pay attention to architecture
- MinGW is not exactly a “vanilla” Windows environment
-
iOS, macOS, watchOS, tvOS
- requires Apple facilities (e.g. Xcode), hence macOS machines
-
Android Native (
androidNative*)- native code for Android (via the NDK), as opposed to the JVM-based
androidtarget
- native code for Android (via the NDK), as opposed to the JVM-based
Gradle as the tool for build automation
-
Building a multi-platform Kotlin project is supported via Gradle (cf. build automation)
- JetBrains’ Amper is an experimental alternative
-
Gradle is a build automation + dependency management system
-
Gradle simultaneously enables & constrains the multi-platform workflow
- pre-defined project structure
- pre-defined development workflow
- enforced code partitioning
- ad-hoc tasks for platform specific/agnostic compilation, testing, deploy, etc.
Kotlin multi-platform project structure (common)
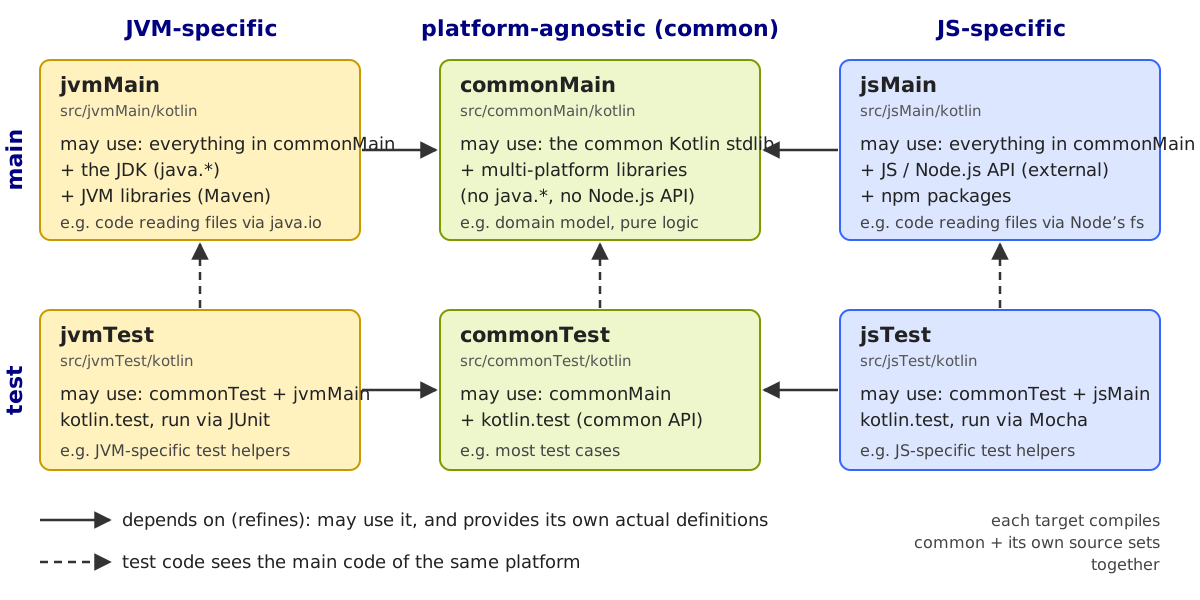
Kotlin enforces strong segregation of the platform-agnostic and platform-specific parts
-
common main code: platform-agnostic code which only depends on:
- the Kotlin std-lib
- plus other third-party Kotlin multi-platform libraries
-
common test code: platform-agnostic test code which only depends on:
- the common main code and all its dependencies
- some Kotlin multi-platform testing library (e.g.
kotlin.testor Kotest)
Kotlin multi-platform project structure (platform-specific)
- for each target platform
T(e.g.jvm,js, etc.)-
T-specific main code: main Kotlin code targeting theTplatform, depending on:- the common main code and all its dependencies
T-specific standard libraryT-specific third-party libraries
-
T-specific test code: test Kotlin code targeting theTplatform, depending on:T-specific main codeT-specific test libraries
-
Kotlin multi-platform project structure (overview)
Kotlin multi-platform project structure (example)
<root>/
│
├── build.gradle.kts        # multi-platform build description
├── settings.gradle.kts     # root project settings
│
└── src/
    ├── commonMain/
    │   └── kotlin/         # platform-agnostic Kotlin code here
    │
    ├── commonTest/
    │   └── kotlin/         # platform-agnostic test code written in Kotlin here
    │
    ├── jvmMain/
    │   ├── java/           # JVM-specific Java code here
    │   ├── kotlin/         # JVM-specific Kotlin code here
    │   └── resources/      # JVM-specific resources here
    ├── jvmTest/
    │   ├── java/           # JVM-specific test code written in Java here
    │   ├── kotlin/         # JVM-specific test code written in Kotlin here
    │   └── resources/      # JVM-specific test resources here
    │
    ├── jsMain/
    │   └── kotlin/         # JS-specific Kotlin code here
    ├── jsTest/
    │   └── kotlin/         # JS-specific test code written in Kotlin here
    │
    ├── <TARGET>Main/
    │   └── kotlin/         # <TARGET>-specific Kotlin code here
    └── <TARGET>Test/
        └── kotlin/         # <TARGET>-specific test code written in Kotlin here
Kotlin multi-platform build configuration (pt. 1)
Defines several aspects of the project:
-
which version of the Kotlin compiler to adopt
plugins { kotlin("multiplatform") version "2.4.21" // defines plugin and compiler version }- better: declare versions in a version catalog (
gradle/libs.versions.toml)
- better: declare versions in a version catalog (
-
which repositories Gradle should use when looking for dependencies
repositories {
    mavenCentral() // use MCR for downloading dependencies (recommended)

    // other custom repositories here (discouraged)
}
Kotlin multi-platform build configuration (pt. 2)
Defines several aspects of the project:
-
which platforms to target (reference here)
kotlin { jvmToolchain(17) // JDK used to compile (and run tests on) the JVM target // declares JVM as target (Java sources in src/jvmMain/java are supported out of the box) jvm() // declares JavaScript as target js { useEsModules() // generate ES modules (or useCommonJs()) binaries.library() // generate a reusable npm package (or binaries.executable()) // the target will consist of a Node project (with NodeJS's stdlib) nodejs { testTask { /* configure Node's testing frameworks */ } } // alternatively, or additionally to nodejs: browser { /* ... */ } } // other targets here } -
other admissible targets:
wasmJs,wasmWasi,android- various native sub-targets (details here)
Kotlin multi-platform build configuration (pt. 3)
- which third-party libraries each target should depend upon
kotlin { sourceSets { // the Kotlin std-lib is added automatically to all source sets commonMain.dependencies { implementation("group.of:multiplatform-library:X.Y.Z") // or api } commonTest.dependencies { // kotlin.test, automatically resolved to the right variant for each target implementation(kotlin("test")) } jvmMain.dependencies { implementation("group.of:jvm-library:X.Y.Z") // or api } jsMain.dependencies { implementation(npm("npm-module", "X.Y.Z")) // lookup on https://www.npmjs.com } } }- platform-specific test source sets (e.g.
jvmTest,jsTest) can declare their own dependencies too
- platform-specific test source sets (e.g.
Kotlin multi-platform build configuration (pt. 4)
-
configure Kotlin compiler options, for all targets (or per target, e.g.
jvm { compilerOptions { ... } })kotlin { compilerOptions { // source compatibility with the specified version of Kotlin languageVersion = KotlinVersion.KOTLIN_2_3 // allows using declarations only from the specified version of Kotlin bundled libraries apiVersion = KotlinVersion.KOTLIN_2_3 // allows using the specified opt-in API optIn.add("kotlin.ExperimentalUnsignedTypes") // annotation FQ-name // enables progressive mode progressiveMode = true // false by default // turns warnings into errors allWarningsAsErrors = true } } -
details about:
Build configuration: full example
plugins {
    kotlin("multiplatform") version "2.4.21"
}

repositories {
    mavenCentral()
}

kotlin {
    jvmToolchain(17)
    jvm()
    js {
        useEsModules()
        binaries.library()
        nodejs()
    }
    compilerOptions {
        allWarningsAsErrors = true
    }
    sourceSets {
        commonMain.dependencies {
            implementation("group.of:multiplatform-library:X.Y.Z")
        }
        commonTest.dependencies {
            implementation(kotlin("test"))
        }
        jvmMain.dependencies {
            implementation("group.of:jvm-library:X.Y.Z")
        }
        jsMain.dependencies {
            implementation(npm("npm-module", "X.Y.Z"))
        }
    }
}
- The build file of the running example is here
Gradle tasks for multi-platform projects (pt. 1)
Let T denote the target name (e.g. jvm, js, etc.); recall Gradle’s lifecycle tasks from the build automation lecture
-
<T>MainClassescompiles the main code for platformT- e.g.
jvmMainClasses,jsMainClasses
- e.g.
-
<T>TestClassescompiles the test code for platformT- e.g.
jvmTestClasses,jsTestClasses
- e.g.
-
<T>Jarcompiles the main code for platformTand produces a JAR out of it- e.g.
jvmJar,jsJar - depends on (hence implies)
<T>MainClasses, but NOT<T>TestClasses
- e.g.
-
<T>Testexecutes tests for platformT- e.g.
jvmTest,jsTest - depends on (hence implies)
<T>MainClasses, AND on<T>TestClasses jsTestaggregatesjsNodeTestandjsBrowserTest(depending on the enabled sub-targets)
- e.g.
Gradle tasks for multi-platform projects (pt. 2)
-
jsProductionExecutableCompileSync(resp.jsProductionLibraryCompileSync) compiles the JS main code into a Node project- requires the
jstarget to be enabled - requires the
binaries.executable()(resp.binaries.library()) configuration to be enabled
- requires the
-
assemblecreates all JARs / klibs (hence compiling the main code for all platforms)- it also generates documentation and sources JARs
- if publishing is configured
- it also generates documentation and sources JARs
-
allTestsexecutes tests for all platforms, and creates an aggregated report -
checklikeallTestsbut it may also include other checks (e.g. style) if configured -
build$\approx$check+assemble
Multi-platform Kotlin sources (common)
-
Ordinary Kotlin sources
-
When in
common:- only the platform-agnostic std-lib can be used
- API reference here (filter by the
Commonplatform)
- API reference here (filter by the
- one may use third-party libraries, as long as they are multi-platform too
- one may use the
expectkeyword - one may use platform-specific annotations
- e.g.
@JvmStatic,@JsName, etc.
- e.g.
- only the platform-agnostic std-lib can be used
Multi-platform Kotlin sources (platform-specific)
Let T denote some target platform
-
When in
T-specific source sets- one may use the
T-specific std-lib - one may use the
T-specific Kotlin libraries - one may use the
T-specific libraries - one may use the
actualkeyword
- one may use the
-
Each platform
Tmay allow for specific keywords- e.g. the
externalmodifier
- e.g. the
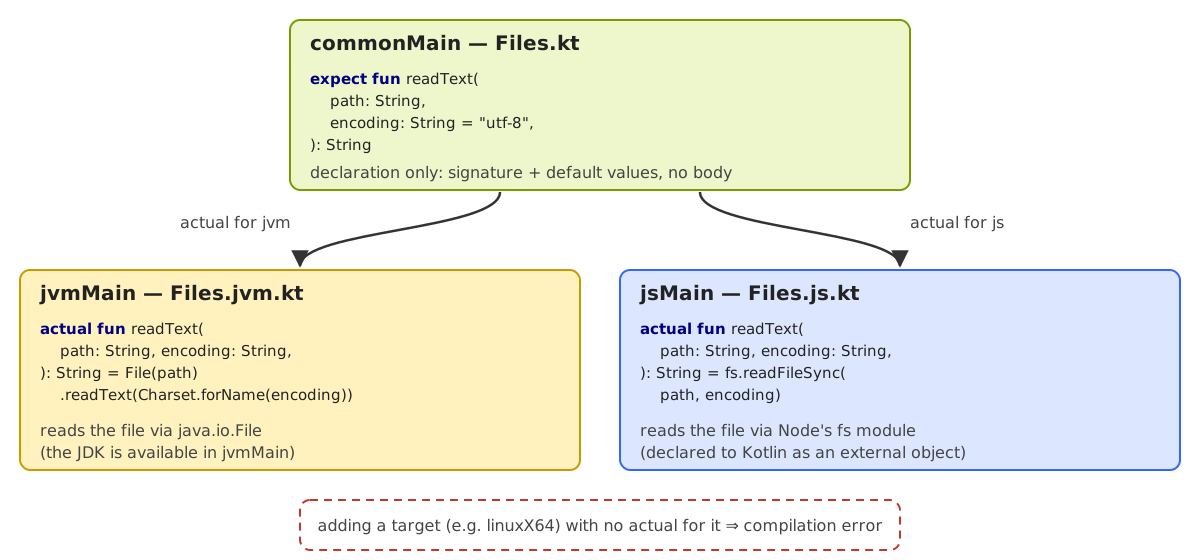
The expect/actual mechanism for specialising common API
-
Declaring an
expected function / type declaration in common code… -
… enforces the existence of a corresponding
actualdefinition for all platforms- compiler won’t succeed until an actual definition is provided for each target
Workflow (top-down)
-
Draw a platform-agnostic design for your domain entities
- keep in mind that you can only rely on a very small std-lib / runtime
- keep in mind that some APIs may be missing from the common std-lib:
- e.g. file system APIs
- try to reason in a platform-agnostic way
- e.g. file system makes no sense for in-browser JS
- separate interfaces from classes
- rely on abstract classes with template methods to maximise common code
- use
expectkeyword to declare platform-agnostic factories
-
Assess the abstraction gap, for each target platform
-
For each target platform:
- draw a platform-specific design extending the platform-agnostic one
- … and filling the abstraction gap for that target
- implement interfaces via platform-specific classes
- implement platform-specific concrete classes for common abstract classes
- use
actualkeyword to implement platform-specific factories
Running example
Multi-platform CSV parsing lib
-
CSV (comma-separated values) files, e.g.:
# HEADER_1, HEADER_2, HEADER_3, ... # character '#' denotes the beginning of a single-line comment # first line conventionally denotes column names (headers) field1, field2, field3, ... # character ',' acts as field separator "field with spaces", "another field, with comma", "yet another field", ... # character '"' acts as field delimiter # other characters may be used to denote comments, separators, or delimiters -
JVM and JS std-lib do not provide direct support for CSV
-
Requirements:
- library for parsing / manipulating CSV files
- parsing = loading from file
- manipulating = creating / editing / saving CSV files, programmatically
- support for both JVM and JS
About the example
-
We’ll follow a domain-driven approach:
- focus on designing / implementing the domain entities
- then, we’ll add functionalities for manipulating them
- finally, we’ll write unit and integration tests
-
Domain entities (can be realised as common code):
Table: in-memory representation of a CSV fileRow: generic row in a CSV fileHeader: special row containing the names of the columnsRecord: special row containing the values of a line in a CSV file
-
Main functionalities (some of which require platform-specific code):
- creating a
Tableprogrammatically - reading columns, rows, and values from a
Table - parsing a CSV file into a
Table - saving a
Tableinto a CSV file
- creating a
-
Full code:
unibo-spe/multiplatform-example(modulecsv-core)
Domain entities
top to bottom direction

package "kotlin" {
    interface Iterable<T>
}

package "io github gciatto csv" {

    interface Row {
        + get(index: Int): String
        + size: Int
    }

    Row -up-|> Iterable: //T// = String

    interface Header {
        + columns: List<String>
        + contains(column: String): Boolean
        + indexOf(column: String): Int
    }

    Row <|-- Header

    interface Record {
        + header: Header
        + values: List<String>
        + contains(value: String): Boolean
        + get(column: String): String
    }

    Row <|-- Record

    Record "*" *-right- "1" Header

    interface Table {
        + header: Header
        + records: List<Record>
        + get(row: Int): Row
        + size: Int
    }

    Table "*" *-u- "1" Header
    Table "*" o-u- "*" Record
    Table -u----|> Iterable: //T// = Row
}
The Row interface
/** Represents a single row in a CSV file. */
@JsExport
interface Row : Iterable<String> {
    /** Gets the value of the field at the given index. */
    @JsName("getByIndex")
    operator fun get(index: Int): String

    /** Gets the number of fields in this row. */
    @JsName("size")
    val size: Int
}- Please ignore the
@JsExportand@JsNameannotations for now, they are explained later
The Header interface
/** Represents the header of a CSV file, i.e. a special row containing the names of the columns. */
@JsExport
interface Header : Row {
    /** Gets the names of the columns. */
    @JsName("columns")
    val columns: List<String>

    /** Checks whether the given column name is present in this header. */
    @JsName("contains")
    operator fun contains(column: String): Boolean

    /** Gets the index of the given column name (-1 if missing). */
    @JsName("indexOf")
    fun indexOf(column: String): Int
}
The Record interface
/** Represents a record in a CSV file. */
@JsExport
interface Record : Row {
    /** Gets the header of this record (useful to know column names). */
    @JsName("header")
    val header: Header

    /** Gets the values of the fields in this record. */
    @JsName("values")
    val values: List<String>

    /** Checks whether the given value is present in this record. */
    @JsName("contains")
    operator fun contains(value: String): Boolean

    /** Gets the value of the field in the given column. */
    @JsName("getByName")
    operator fun get(column: String): String
}
The Table interface
/** Represents a table, i.e. an in-memory representation of a CSV file. */
@JsExport
interface Table : Iterable<Row> {
    /** Gets the header of this table (useful to know column names). */
    @JsName("header")
    val header: Header

    /** Gets the records in this table. */
    @JsName("records")
    val records: List<Record>

    /** Gets the row at the given index (0 is the header). */
    @JsName("get")
    operator fun get(row: Int): Row

    /** Gets the number of rows in this table (header included). */
    @JsName("size")
    val size: Int
}
Common implementations of domain entities
<p>top to bottom direction</p>
<p>package “io github gciatto csv <strong>impl</strong>” {
interface Row</p>
<pre><code>abstract class AbstractRow {
- values: List<String>
# constructor(values: List<String>)
# toString(type: String?): String
}
Row <|-d- AbstractRow
interface Header
class DefaultHeader {
- indexesByName: Map<String, Int>
+ constructor(columns: Iterable<String>)
}
Row <|-d- Header
Header <|-d- DefaultHeader
AbstractRow <|-d- DefaultHeader
interface Record
class DefaultRecord {
+ constructor(header: Header, values: Iterable<String>)
}
Row <|-d- Record
Record <|-- DefaultRecord
AbstractRow <|-d- DefaultRecord
class DefaultTable {
+ constructor(header: Header, records: Iterable<Record>)
}
interface Table
Table <|-- DefaultTable
</code></pre>
<p>}</p>
The AbstractRow class
internal abstract class AbstractRow(protected open val values: List<String>) : Row {
    override val size: Int
        get() = values.size

    override fun get(index: Int): String = values[index]
    override fun equals(other: Any?): Boolean {
        if (this === other) return true
        if (other == null || this::class != other::class) return false

        other as AbstractRow

        return values == other.values
    }

    override fun hashCode(): Int = values.hashCode()

    protected fun toString(type: String?): String {
        var prefix = ""
        var suffix = ""
        if (type != null) {
            prefix = "$type("
            suffix = ")"
        }
        return values.joinToString(", ", prefix, suffix) { "\"$it\"" }
    }

    override fun toString(): String = toString("Row")

    override fun iterator(): Iterator<String> = values.iterator()
}- Base implementation for the
Rowinterface:toString(type)renders rows as<type>("field1", "field2", ...)
The DefaultHeader class
internal class DefaultHeader(columns: Iterable<String>) : Header, AbstractRow(columns.toList()) {
    private val indexesByName by lazy {
        values.mapIndexed { index, name -> name to index }.toMap()
    }

    override val columns: List<String>
        get() = values

    override fun contains(column: String): Boolean = column in indexesByName.keys

    override fun indexOf(column: String): Int = indexesByName[column] ?: -1

    override fun iterator(): Iterator<String> = values.iterator()

    override fun toString(): String = toString("Header")
}indexesByNameis a lazily-computed cache of column indexes, for faster lookup
The DefaultRecord class
internal class DefaultRecord(
    override val header: Header,
    values: Iterable<String>
) : Record, AbstractRow(values.toList()) {

    init {
        require(header.size == super.values.size) {
            "Inconsistent amount of values (${super.values.size}) w.r.t. header size (${header.size})"
        }
    }

    override fun contains(value: String): Boolean = values.contains(value)

    override val values: List<String>
        get() = super.values

    override fun get(column: String): String =
        header.indexOf(column).takeIf { it in 0..< size }?.let { values[it] }
            ?: throw NoSuchElementException("No such column: $column")

    override fun toString(): String = toString("Record")
}
The DefaultTable class
internal class DefaultTable(override val header: Header, records: Iterable<Record>) : Table {
    // Eager, defensive copy of the records
    override val records: List<Record> = records.toList()

    override fun get(row: Int): Row = if (row == 0) header else records[row - 1]

    override val size: Int
        get() = records.size + 1

    override fun iterator(): Iterator<Row> = (sequenceOf(header) + records.asSequence()).iterator()
    override fun equals(other: Any?): Boolean {
        if (this === other) return true
        if (other !is DefaultTable) return false
        if (header != other.header) return false
        if (records != other.records) return false

        return true
    }

    override fun hashCode(): Int {
        var result = header.hashCode()
        result = 31 * result + records.hashCode()
        return result
    }

    override fun toString(): String = joinToString(", ", "Table(", ")")
}
Need for factory methods
-
To enforce separation between API and implementation code, it’s better:
- to keep interfaces public, and classes internal
- to provide factory methods for creating instances of the interfaces
-
Convention in Kotlin is to create factory methods as package-level
functions- e.g. contained into the
io/github/gciatto/csv/Csv.ktfile
- e.g. contained into the
-
Factory methods may be named after the concept they create:
<concept>Of(args...)- e.g.
headerOf(columns...),recordOf(header, values...), etc.
- e.g.
-
Class diagram:
    @startuml
    skinparam monochrome false
    class Csv{
        + headerOf(columns): Header
        + anonymousHeader(size: Int): Header
        ..
        + recordOf(header, values): Record
        ..
        + tableOf(header, records): Table
        + tableOf(rows): Table
    }
    @enduml
The Csv.kt file (pt. 1)
Factories for headers (possibly anonymous, i.e. with columns named after their index), records, and tables:
fun headerOf(columns: Iterable<String>): Header = DefaultHeader(columns)

@JsExport
fun headerOf(vararg columns: String): Header = headerOf(columns.asIterable())
fun headerOf(columns: Sequence<String>): Header = headerOf(columns.asIterable())

@JsExport
fun anonymousHeader(size: Int): Header = headerOf((0 ..< size).map { it.toString() })

fun recordOf(header: Header, columns: Iterable<String>): Record = DefaultRecord(header, columns)

@JsExport
fun recordOf(header: Header, vararg columns: String): Record = recordOf(header, columns.asIterable())
fun recordOf(header: Header, columns: Sequence<String>): Record = recordOf(header, columns.asIterable())

fun tableOf(header: Header, records: Iterable<Record>): Table = DefaultTable(header, records)

@JsExport
@JsName("table")
fun tableOf(header: Header, vararg records: Record): Table = tableOf(header, records.asIterable())
fun tableOf(header: Header, records: Sequence<Record>): Table = tableOf(header, records.asIterable())- Notice that each factory method is overloaded
- to support
Iterable,Sequence, andvarargarguments - this is convenient for Kotlin programmers who will use our library
- to support
The Csv.kt file (pt. 2)
Table creation from rows (anonymous header if none is provided):
fun tableOf(rows: Iterable<Row>): Table {
    val records = mutableListOf<Record>()
    var header: Header? = null
    for (row in rows) {
        when (row) {
            is Header -> header = row
            is Record -> records.add(row)
        }
    }
    require(header != null || records.isNotEmpty())
    return tableOf(header ?: anonymousHeader(records[0].size), records)
}

@JsExport
@JsName("tableOf")
fun tableOf(vararg rows: Row): Table = tableOf(rows.asIterable())

fun tableOf(rows: Sequence<Row>): Table = tableOf(rows.asIterable())
Time for unit testing (pt. 1)
Dummy instances object, in Tables.kt:
object Tables {
    val irisShortHeader = headerOf("sepal_length", "sepal_width", "petal_length", "petal_width", "class")

    val irisLongHeader = headerOf(
        "sepal length in cm",
        "sepal width, in cm",
        "petal length",
        "petal width",
        "class"
    )

    fun iris(header: Header): Table = tableOf(
        header,
        recordOf(header, "5.1", "3.5", "1.4", "0.2", "Iris-setosa"),
        recordOf(header, "4.9", "3.0", "1.4", "0.2", "Iris-setosa"),
        recordOf(header, "4.7", "3.2", "1.3", "0.2", "Iris-setosa")
    )
}
Time for unit testing (pt. 2)
Some basic tests in TestCSV.kt (bad way of writing test methods, don’t do this at home):
    @Test
    fun recordBasics() {
        val record = Tables.iris(Tables.irisShortHeader).records[0]
        assertEquals("5.1", record[0])
        assertEquals("5.1", record["sepal_length"])
        assertEquals("3.5", record[1])
        assertEquals("3.5", record["sepal_width"])
        assertEquals("1.4", record[2])
        assertEquals("1.4", record["petal_length"])
        assertEquals("0.2", record[3])
        assertEquals("0.2", record["petal_width"])
        assertEquals("Iris-setosa", record[4])
        assertEquals("Iris-setosa", record["class"])
        assertFailsWith<IndexOutOfBoundsException> { record[5] }
        assertFailsWith<NoSuchElementException> { record["missing"] }
}- Run tests via Gradle task
allTests(also try to run tests for specific platforms, e.g.jvmTestorjsTest)
Summary of what we did so far
-
We designed a set of domain entities
Row,Header,Record,Table- we provided a set of factory methods for creating instances of those entities
-
We implemented the domain entities as common code
-
We wrote some unit tests for the domain entities
- again as common code
-
Let’s focus now on more complex functionalities
- e.g. parsing a CSV file into a
Table - e.g. saving a
Tableinto a CSV file - all such features require I/O functionalities
- e.g. parsing a CSV file into a
I/O is platform-specific, hence we need platform-specific code
How much platform-specific code is needed?
-
I/O functionalities are supported by fairly different APIs in the JVM and JS
- e.g. JVM’s
java.iopackage vs. JS’fsmodule - sadly, Kotlin std-lib does not provide a common API for I/O
- e.g. JVM’s
-
Do we need to rewrite the same business logic twice? (once for JVM, once for JS)
- yes, but we can minimise the amount of code to be rewritten
-
Let’s try to decompose the problem as follows:
- parsing CSV into
Table: file $\rightarrow$ string(s) $\rightarrow$Table - saving
Tableas CSV file:Table$\rightarrow$ string(s) $\rightarrow$ file
- parsing CSV into
-
Remarks:
- only the “file $\leftrightarrow$ string(s)” part is platform-specific
- conversely, the “string(s) $\leftrightarrow$
Table” part is platform-agnostic- let’s realise this one first, as common code
Three more entities to be modelled
-
Configuration: set of characters to be used to parse / represent CSV files- e.g. separator, delimiter, comment, etc.
-
Formatter: convertsRows into strings, according to someConfiguration -
Parser: converts some source into aTable, according to someConfiguration- source $\approx$ anything that can be interpreted as a string to be parsed (e.g. file, string, etc.)
@startuml
skinparam monochrome false

package "io github gciatto csv" {

    class Configuration {
        + separator: Char
        + delimiter: Char
        + comment: Char
        --
        + isComment(string: String): Boolean
        + isRecord(string: String): Boolean
        + isHeader(string: String): Boolean
        ..
        + getComment(string: String): String?
        + getFields(string: String): List<String>
        + getColumnNames(string: String): List<String>
    }

    interface Formatter {
        + source: Iterable<Row>
        + configuration: Configuration
        + format(): Iterable<String>
    }

    interface Parser {
        + source: Any
        + configuration: Configuration
        + parse(): Iterable<Row>
    }

    Formatter "1" o-- "1" Configuration
    Parser "1" o-- "1" Configuration

}
@enduml
The Configuration class
data class Configuration(val separator: Char, val delimiter: Char, val comment: Char) {
    // Checks whether the given string is a comment (i.e. starts with the comment character).
    fun isComment(string: String): Boolean = TODO()

    // Gets the content of the comment line (i.e. removes the initial comment character).
    fun getComment(string: String): String? = TODO()

    // Checks whether the given string is a record (i.e. it contains at least one field)
    fun isRecord(string: String): Boolean = TODO()

    // Retrieves the fields in the given record (i.e. splits the string at the separator character)
    fun getFields(string: String): List<String> = TODO()

    // Checks whether the given string is a header (i.e. a comment whose content is a record)
    fun isHeader(string: String): Boolean = TODO()

    // Retrieves the column names in the given header
    fun getColumnNames(string: String): List<String> = TODO()
}
- implementation of methods is long and boring, but straightforward
- it relies on regular expressions, which are supported by Kotlin’s common std-lib
- details in Configuration.kt
The Formatter interface
/** Converts rows into strings, according to some [Configuration]. */
@JsExport
interface Formatter {
    /** The source of this formatter (i.e. the rows to be formatted). */
    @JsName("source")
    val source: Iterable<Row>

    /** The configuration of this formatter (i.e. the characters to be used). */
    @JsName("configuration")
    val configuration: Configuration

    /** Formats the source into a sequence of strings (one for each row in the source). */
    @JsName("format")
    fun format(): Iterable<String>
}
The Parser interface
/** Converts some source into rows, according to some [Configuration]. */
@JsExport
interface Parser {
    /** The source to be parsed by this parser (must be interpretable as string). */
    @JsName("source")
    val source: Any

    /** The configuration of this parser (i.e. the characters to be used). */
    @JsName("configuration")
    val configuration: Configuration

    /** Parses the source into a sequence of rows (one for each row in the source). */
    @JsName("parse")
    fun parse(): Iterable<Row>
}
Common implementation of novel entities
@startuml
skinparam monochrome false

package "io github gciatto csv impl" {

    class Configuration
    interface Formatter
    interface Parser

    DefaultFormatter "1" o-- "1" Configuration
    AbstractParser "1" o-- "1" Configuration

    class DefaultFormatter {
        + constructor(source: Iterable<Row>, configuration: Configuration)
        - formatRow(row: Row): String
        - formatAsHeader(row: Row): String
        - formatAsRecord(row: Row): String
    }

    Formatter <|-- DefaultFormatter

    abstract class AbstractParser {
        # constructor(source: Any, configuration: Configuration)
        # beforeParsing()
        # afterParsing()
        # {abstract} sourceAsLines(): Sequence<String>
    }

    Parser <|-- AbstractParser

    class StringParser {
        + source: String
        + constructor(source: String, configuration: Configuration)
        + sourceAsLines(): Sequence<String>
    }

    AbstractParser <|-- StringParser
}
@enduml
The DefaultFormatter class
internal class DefaultFormatter(
    override val source: Iterable<Row>,
    override val configuration: Configuration
) : Formatter {
    override fun format(): Iterable<String> = source.asSequence().map(this::formatRow).asIterable()

    private fun formatAsHeader(header: Header): String = "${configuration.comment} ${formatAsRecord(header)}"

    private fun formatAsRecord(row: Row): String =
        row.joinToString("${configuration.separator} ") {
            val delimiter = configuration.delimiter
            "$delimiter$it$delimiter"
        }

    private fun formatRow(row: Row): String = when (row) {
        is Header -> formatAsHeader(row)
        else -> formatAsRecord(row)
    }
}formatlazily converts each row into a string: headers are prefixed by the comment character, fields are wrapped by the delimiter character
The AbstractParser class (pt. 1)
internal abstract class AbstractParser(
    override val source: Any,
    override val configuration: Configuration
) : Parser {

    // Hooks to be overridden by sub-classes to initialise / finalise parsing (e.g. open / close files)
    protected open fun beforeParsing() = Unit
    protected open fun afterParsing() = Unit

    // Template method that splits the source into a sequence of strings (one per line)
protected abstract fun sourceAsLines(): Sequence<String>beforeParsing/afterParsingare hooks,sourceAsLinesis the abstract step of a template method
The AbstractParser class (pt. 2)
    override fun parse(): Iterable<Row> = sequence {
        beforeParsing()
        try {
            var header: Header? = null
            for ((i, line) in sourceAsLines().withIndex()) {
                if (line.isBlank()) {
                    continue
                } else if (configuration.isHeader(line)) {
                    if (header == null) {
                        header = headerOf(configuration.getColumnNames(line))
                        yield(header)
                    }
                } else if (configuration.isComment(line)) {
                    continue
                } else if (configuration.isRecord(line)) {
                    val fields = configuration.getFields(line)
                    if (header == null) {
                        header = anonymousHeader(fields.size)
                        yield(header)
                    }
                    try {
                        yield(recordOf(header, fields))
                    } catch (e: IllegalArgumentException) {
                        throw IllegalStateException("Invalid CSV at line ${i + 1}: $line", e)
                    }
                } else {
                    error("Invalid CSV at line ${i + 1}: $line")
                }
            }
        } finally {
            afterParsing() // executed even in case of errors
        }
    }.asIterable()
sequence { ... yield(...) }produces rows lazily, one at a timefinallyensuresafterParsing()is called upon errors too (not if the consumer stops iterating early)
The StringParser class
internal class StringParser(override val source: String, configuration: Configuration) : AbstractParser(source, configuration) {
    override fun sourceAsLines(): Sequence<String> = source.lineSequence()
}- it simply splits the source string into lines
Providing functionalities via extension methods
Additions to the Csv.kt file:
const val DEFAULT_SEPARATOR = ','
const val DEFAULT_DELIMITER = '"'
const val DEFAULT_COMMENT = '#'
@JsExport
fun Iterable<Row>.formatAsCSV(
separator: Char = DEFAULT_SEPARATOR,
delimiter: Char = DEFAULT_DELIMITER,
comment: Char = DEFAULT_COMMENT
): String = DefaultFormatter(this, Configuration(separator, delimiter, comment)).format().joinToString("\n")
@JsExport
fun String.parseAsCSV(
separator: Char = DEFAULT_SEPARATOR,
delimiter: Char = DEFAULT_DELIMITER,
comment: Char = DEFAULT_COMMENT
): Table = StringParser(this, Configuration(separator, delimiter, comment)).parse().let(::tableOf)formatAsCSVconverts any container of rows into a CSV string,parseAsCSVparses a CSV string into a table
Unit tests and usage examples (pt. 1)
Dummy instances for testing (other constants in CsvStrings.kt):
object CsvStrings {
    val iris: String = """
    |# sepal_length, sepal_width, petal_length, petal_width, class
    |5.1,3.5,1.4,0.2,Iris-setosa
    |4.9,3.0,1.4,0.2,Iris-setosa
    |4.7,3.2,1.3,0.2,Iris-setosa
    """.trimMargin()

    val irisWellFormatted: String = """
    |# "sepal_length", "sepal_width", "petal_length", "petal_width", "class"
    |"5.1", "3.5", "1.4", "0.2", "Iris-setosa"
    |"4.9", "3.0", "1.4", "0.2", "Iris-setosa"
    |"4.7", "3.2", "1.3", "0.2", "Iris-setosa"
    """.trimMargin()
Unit tests and usage examples (pt. 2)
Tests involving parsing be like:
    @Test
    fun parsingFromCleanString() {
        val iris: Table = CsvStrings.iris.parseAsCSV()
        assertEquals(
            expected = Tables.iris(Tables.irisShortHeader),
            actual = iris
        )
    }
Tests involving formatting be like:
    @Test
    fun formattingToString() {
        val iris: Table = Tables.iris(Tables.irisShortHeader)
        assertEquals(
            expected = CsvStrings.irisWellFormatted,
            actual = iris.formatAsCSV()
        )
    }
Time to go platform-specific
- Further additions to the
Csv.ktfile (reading and parsing a CSV file from the given path):
expect fun parseCsvFile(
    path: String,
    separator: Char = DEFAULT_SEPARATOR,
    delimiter: Char = DEFAULT_DELIMITER,
    comment: Char = DEFAULT_COMMENT
): Table- notice the
expectkeyword, and the lack of function body - we’re just declaring the signature of a platform-specific function
- there is no type for representing paths in Kotlin’s common std-lib
- hence we’re using
Stringas a platform-agnostic representation of paths- this is a suboptimal choice
- hence we’re using
Time to go platform-specific on the JVM (pt. 1)
-
I/O (over textual files) is mainly supported by means of the following classes:
-
Buffered readers support reading a file line-by-line
-
On Kotlin/JVM, Java’s std-lib is available as Kotlin’s std-lib
- hence, we may use Java’s std-lib directly
- the abstraction gap is close to 0
-
We may simply create a new sub-type of
AbstractParser- using
Files as sources - creating a
BufferedReaderbehind the scenes to read files line-by-line
- using
Time to go platform-specific on the JVM (pt. 2)
In the jvmMain source set
A JVM-specific parser, FileParser.kt:
internal class FileParser(override val source: File, configuration: Configuration) : AbstractParser(source, configuration) {
    private lateinit var reader: BufferedReader

    override fun beforeParsing() {
        reader = source.bufferedReader()
    }

    override fun afterParsing() {
        reader.close()
    }

    override fun sourceAsLines(): Sequence<String> = reader.lines().asSequence()
}- the source is now forced to be a
File - the
lateinitreader is opened before parsing, and closed afterwards - the file is read lazily, line-by-line
Time to go platform-specific on the JVM (pt. 3)
The Csv.jvm.kt file:
@file:JvmName("CsvJvm")

package io.github.gciatto.csv

import java.io.File
import kotlin.jvm.JvmName

actual fun parseCsvFile(
    path: String,
    separator: Char,
    delimiter: Char,
    comment: Char
): Table = FileParser(File(path), Configuration(separator, delimiter, comment)).parse().let(::tableOf)- this is how
parseCsvFileis implemented on the JVM - notice the
actualkeyword, and the presence of a function body - notice the usage of
FileParserin the function bodyFileParseris aninternalclass filling the abstraction gap on the JVM
@file:JvmNameis explained later
Time to go platform-specific on the JS (pt. 1)
-
I/O (over textual files) is mainly supported by means of the following things:
-
These functions support reading / writing a file in one shot
- i.e. they return / generate the whole content of the file as a string
- quite inefficient if the file is big
-
On Kotlin/JS, Node’s std-lib is not directly available
- one must instruct the compiler about
- where to look up std-lib functions (module name)
- how to map JS functions to Kotlin functions (
externaldeclarations)
- the abstraction gap is non-negligible
- one must instruct the compiler about
-
To-do list for Kotlin/JS:
- create
externaldeclarations for the Node’s std-lib functions to be used - implement JS-specific code via the
StringParser(after reading the whole file)
- create
Time to go platform-specific on the JS (pt. 2)
In the jsMain source set
First, let’s create the NodeFs.kt file (containing external declarations for the fs module):
@file:JsModule("fs")

package io.github.gciatto.csv

external fun readFileSync(path: String, options: dynamic = definedExternally): String

external fun writeFileSync(file: String, data: String, options: dynamic = definedExternally)- Kotlin mappings for
readFileSyncandwriteFileSync - the
@file:JsModule("fs")annotation instructs the compiler that the declarations of this file come from thefsmodule externaldeclarations are Kotlin signatures of JS functionsdynamicis a special type that can be used to represent any JS object- it overrides Kotlin’s type system, hence it should be used with care
- it prevents developers from declaring too much
externalstuff - good to use when the JS API is not known in advance or uses union types
definedExternallyis stating that a parameter is optional (default value is defined in JS)
Time to go platform-specific on the JS (pt. 3)
Then, let’s create the Csv.js.kt file containing:
@JsExport
actual fun parseCsvFile(
    path: String,
    separator: Char,
    delimiter: Char,
    comment: Char
): Table = readFileSync(path, js("{encoding: 'utf8'}")).parseAsCSV(separator, delimiter, comment)- this is how the
parseCsvFileis implemented on JS - notice the
actualkeyword, and the presence of a function body - notice the usage of
readFileSyncto read a file as a string in one shot - notice the exploitation of common code for parsing the string into a
Table(namely,parseAsCSV) @JsExportmakes the function callable from JS code (see later)- notice the
js("...")magic function- it allows JS code to be written directly in Kotlin
- the provided string should contain bare JS code, which the compiler will output as-is
- it’s a way to fill the abstraction gap on JS
- we use it to create a JS object on the fly, to provide optional parameters to
readFileSync
How much platform-specific code did we write?
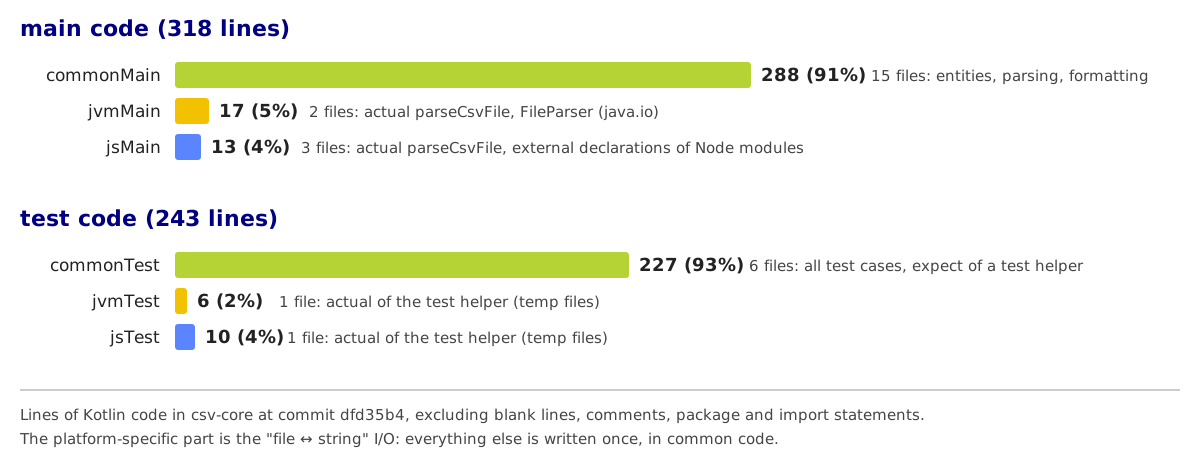
- Recall the plan: only the “file $\leftrightarrow$ string(s)” part is platform-specific
Platform-agnostic testing (strategy)
-
We may test our CSV library in common-code
- so as to avoid repeating testing code
-
The test suite may:
- create temporary files with known paths, containing known CSV data
- read those paths, and parse them as CSV
- assert that the parsed tables are as expected
-
The hard part is step 1: two platform-specific steps
- discovering the temp directory of the current system
- writing a file
Multi-platform testing (preliminaries, pt. 1)
- file Utils.kt in
commonTest(creates a temporary file with the given name and content, and returns its path):
internal fun String.splitExtension(): Pair<String, String> {
    val splitted = split(".")
    return if (splitted.size > 1) {
        splitted.subList(0, splitted.lastIndex).joinToString(".") to splitted.last()
    } else {
        this to ""
    }
}

expect fun createTempFile(name: String, content: String): String-
notice the
expected function -
file Utils.jvm.kt in
jvmTest:
actual fun createTempFile(name: String, content: String): String {
    val (n, e) = name.splitExtension()
    val file = File.createTempFile(n, ".$e")
    file.writeText(content)
    return file.absolutePath
}- cf. documentation of method
File.createTempFile
Multi-platform testing (preliminaries, pt. 2)
- file NodeOs.kt in
jsMain(externaldeclaration for theosmodule):
@file:JsModule("os")

package io.github.gciatto.csv

external fun tmpdir(): String- file Utils.js.kt in
jsTest:
import kotlin.random.Random

private val tmpDirectory by lazy {
    tmpdir()
}

actual fun createTempFile(name: String, content: String): String {
    val (n, e) = name.splitExtension()
    val tag = Random.nextLong().toULong()
    val path = "$tmpDirectory/$n-$tag.$e"
    writeFileSync(path, content)
    return path
}- cf. documentation of
os.tmpdir kotlin.random.Randomis part of the common std-lib, so no JS-specific code is needed for random numbers
Multi-platform testing (actual tests)
- file CsvFiles.kt in
commonTest(paths of temporary files, lazily created upon first usage, containing the strings inCsvStrings):
object CsvFiles {
    val iris: String by lazy {
        createTempFile("iris.csv", CsvStrings.iris)
    }

    val irisWellFormatted: String by lazy {
        createTempFile("irisWellFormatted.csv", CsvStrings.irisWellFormatted)
}- tests for parsing (in TestCsvFiles.kt) be like:
    @Test
    fun testParseIris() {
        val parsedFromString = CsvStrings.iris.parseAsCSV()
        val readFromFile = parseCsvFile(CsvFiles.iris)
        assertEquals(parsedFromString, readFromFile)
    }
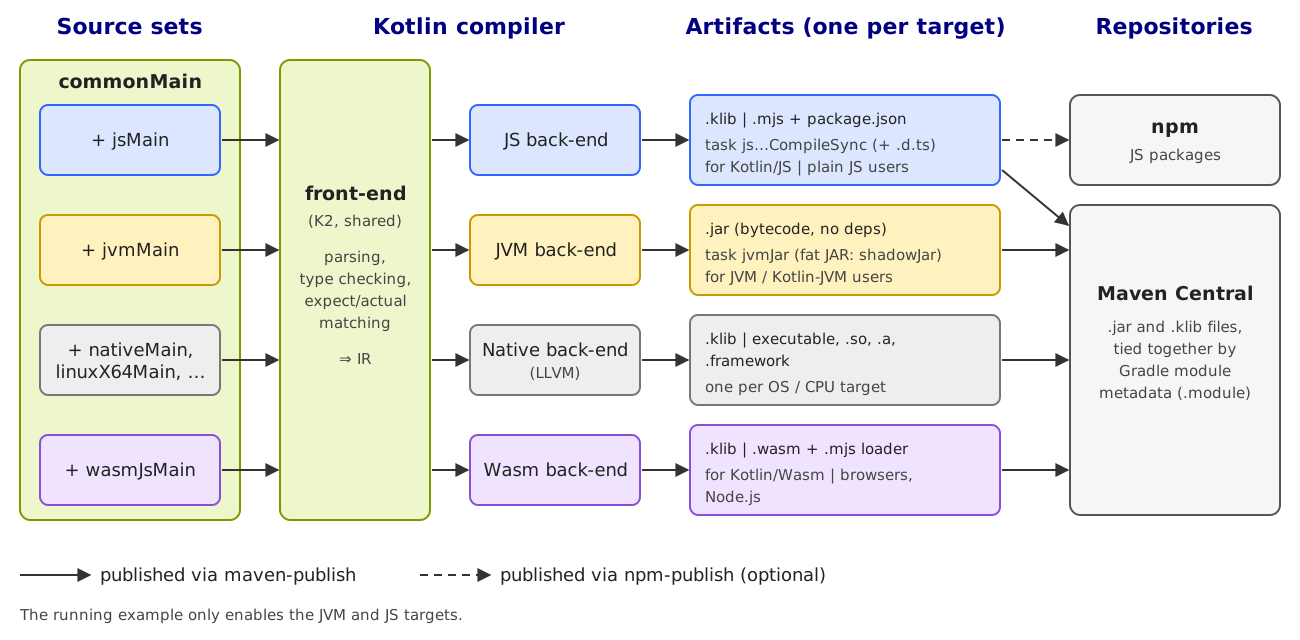
Output of a multi-platform build
-
Kotlin multi-platform libraries are published as a set of artifacts (one per target, plus Gradle module metadata)
- enabling importing the project as a dependency in other multi-platform projects
-
The
jvmMainsource set is compiled into a JVM-compliant JAR- enabling importing the project as a dependency in JVM projects
- enabling the creation of runnable JARs
- via the various
*Jarorassembletasks
-
The
jsMainsource set is compiled into either- a Kotlin library (
.klib), enabling importing the project as a dependency in Kotlin/JS projects- via the various
*Jarorassembletasks
- via the various
- a NodeJS project
- via the
jsProductionExecutableCompileSync(orjsProductionLibraryCompileSync) task
- via the
- a Kotlin library (
Output of JVM compilation
-
Task for JVM-only compilation of re-usable packages:
jvmJar -
Effect:
- compile the project as JVM bytecode
- pack the bytecode into a JAR file
- move the JAR file into
$PROJ_DIR/build/libs/$PROJ_NAME-jvm-$PROJ_VERSION.jar
-
The JAR does not contain dependencies
-
Ad-hoc Gradle plugins or code are needed to create a fat JAR
- e.g. the running example uses the Shadow plugin, cf. task
shadowJar
- e.g. the running example uses the Shadow plugin, cf. task
Output of JS compilation
-
Task for JS-only compilation of re-usable packages:
jsProductionLibraryCompileSync(withbinaries.library())- or
jsProductionExecutableCompileSync(withbinaries.executable())
- or
-
Effect:
- Generate Node project into
$ROOT_PROJ_DIR/build/js/packages/$ROOT_PROJ_NAME-$PROJ_NAME:- JS code (
.mjsfiles, when using ES modules) package.jsonfile
- JS code (
- Dead code elimination removing unused code
- i.e. code which is neither exported nor (indirectly) called by
main
- i.e. code which is neither exported nor (indirectly) called by
- Generate Node project into
-
Support for packing as npm package via the
npm-publishGradle plugin
Output of a multi-platform build (overview)
Calling Kotlin from other platforms
-
Kotlin code can be called from the target platforms’ main languages
- e.g. Java, JavaScript, etc.
-
Understanding the mapping between Kotlin and other languages is key
- it impacts the usability of Kotlin libraries for ordinary platform users
How are Kotlin’s syntactical categories mapped to other platforms/languages?
- the answer varies on a per-platform basis
Kotlin–Java Mapping (pt. 1)
- Kotlin class $\equiv$ Java class
class MyClass {}
interface MyType {}
public class MyClass {}
public interface MyType {}
- No syntactical difference between primitive and reference types
Int$\leftrightarrow$int/Integer,Short$\leftrightarrow$short/Short, etc.
val x: Int = 0
val y: Int? = null
int x = 0;
Integer y = null;
- Some Kotlin types are replaced by Java types at compile time
- e.g.
Any$\rightarrow$Object,kotlin.collections.List$\rightarrow$java.util.List, etc.
- e.g.
val x: Any = "ciao"
val y: kotlin.collections.List<Int> = listOf(1, 2, 3)
val z: kotlin.collections.MutableList<String> = mutableListOf("a", "b", "c")
Object x = "ciao";
java.util.List<Integer> y = java.util.Arrays.asList(1, 2, 3);
java.util.List<String> z = java.util.List.of("a", "b", "c");
- Other Kotlin types are mapped to homonymous Java types
Kotlin–Java Mapping (pt. 2)
- Kotlin properties are mapped to getter / setter methods
interface MyType {
    val x: Int
    var y: String
}
public interface MyType {
    int getX();
    String getY(); void setY(String y);
}
- … unless the
JvmFieldannotation is adopted
import kotlin.jvm.JvmField
class MyType {
    @JvmField
    val x: Int = 0
    @JvmField
    var y: String = ""
}
public class MyType {
    public final int x = 0;
    public String y = "";
}
- Kotlin’s top-level functions in file
X.ktare mapped to static methods of classXKt
// file MyFile.kt
fun f() {}
public final class MyFileKt {
    public static void f() {}
}
- … unless the
JvmNameannotation is exploited (e.g.@file:JvmName("Csv")in ourCsv.kt)
@file:JvmName("MyModule")
import kotlin.jvm.JvmName
fun f() {}
public final class MyModule {
    public static void f() {}
}
Kotlin–Java Mapping (pt. 3)
- Kotlin’s
object Xis mapped to Java classXwith- private constructor
- public static final field named
INSTANCEto access
object MySingleton {}
public final class MySingleton {
    private MySingleton() {}
    public static final MySingleton INSTANCE = new MySingleton();
}
- Class
X’s companion object is mapped to public static final field namedCompanionon classX
class MyType private constructor() {
    companion object {
        fun of(): MyType = MyType()
    }
}

// usage:
val x: MyType = MyType.of()
public class MyType {
    private MyType() {}
    public static final class Companion {
        public MyType of() { return new MyType(); }
    }
    public static final Companion Companion = new Companion();
}

// usage:
MyType x = MyType.Companion.of();
Kotlin–Java Mapping (pt. 4)
- Class
X’s companion object’s memberMtagged with@JvmStaticis mapped to static memberMon classX
import kotlin.jvm.JvmStatic
class MyType private constructor() {
    companion object {
        @JvmStatic
        fun of(): MyType = MyType()
    }
}

// usage:
val x: MyType = MyType.of()
public class MyType {
    private MyType() {}
    public static MyType of() { return new MyType(); }
}

// usage:
MyType x = MyType.of();
- Kotlin’s variadic functions are mapped to Java’s variadic methods
fun f(vararg xs: Int) {
    val ys: IntArray = xs
}
void f(int... xs) {
    int[] ys = xs;
}
- Kotlin’s extension methods are mapped to static Java methods with one more argument (the receiver)
// file MyFile.kt
class MyType { }
fun MyType.myMethod() {}

// usage:
val x = MyType()
x.myMethod() // postfix
public final class MyFileKt {
    public static void myMethod(MyType $this$myMethod) {}
}

// usage:
MyType x = new MyType();
MyFileKt.myMethod(x); // prefix
Kotlin–Java Mapping (pt. 5)
- practical consequence: usability of fluent chains, in Java, is suboptimal
- e.g. sequence operations are implemented as extension methods
import kotlin.sequences.*

val x = (0 ..< 10).asSequence() // 0, 1, 2, ..., 9
    .filter { it % 2 == 0 } // 0, 2, 4, ..., 8
    .map { it + 1 } // 1, 3, 5, ..., 9
    .sum() // 25
import static kotlin.sequences.SequencesKt.*;

int x = sumOfInt(
            map(
                filter(
                    asSequence(
                            new IntRange(0, 9).iterator()
                    ),
                    it -> it % 2 == 0
                ),
                it -> it + 1
            )
        );
- optional arguments exist in Kotlin but they do not exist in Java
fun f(a: Int = 1, b: Int = 2, c: Int = 3) { /* ... */ }

// usage:
f(b = 5)
void f(int a, int b, int c) { /* ... */ }

// usage:
f(1, 5, 3);
Kotlin–Java Mapping (pt. 6)
- practical consequence:
- optional arguments are handy in Kotlin, but…
- … they are painful to use in Java
- mitigation strategy: use
@JvmOverloadsto generate overloaded methods for Java- by design, the annotation only generates overloads dropping trailing parameters
import kotlin.jvm.JvmOverloads

@JvmOverloads
fun f(a: Int = 1, b: Int = 2, c: Int = 3) { /* ... */ }
void f(int a, int b, int c) { /* ... */ }
void f(int a, int b) { f(a, b, 3); }
void f(int a) { f(a, 2, 3); }
void f() { f(1, 2, 3); }

// overloads that are not generated (some would even clash, having the same JVM signature):
// void f(int a, int c) { f(a, 2, c); }
// void f(int b, int c) { f(1, b, c); }
// void f(int c) { f(1, 2, c); }
// void f(int b) { f(1, b, 3); }
Kotlin–Java Mapping (pt. 7)
-
Kotlin has no checked exceptions: use
@Throwsto let Java callers catch them@Throws(IOException::class) fun readFile(path: String): String { /* ... */ } // Java: String readFile(String path) throws IOException -
Kotlin’s nullability is exposed to Java via annotations (
@NotNull,@Nullable)- Java types are seen in Kotlin as platform types (e.g.
String!), whose nullability is unknown
- Java types are seen in Kotlin as platform types (e.g.
-
internalmembers arepublicin the bytecode, but their names are mangled- e.g.
internal fun f()in modulecsv-corebecomesf$csv_core(), which is discouraging to call from Java
- e.g.
-
Reference: calling Kotlin from Java
Kotlin–Java Mapping Example
-
Compile our CSV lib and import it as a dependency in a novel Java library
-
Alternatively, add Java sources to the
jvmTestsource set, and use the library -
Listen to the teacher presenting key points
Kotlin–JavaScript Mapping (pt. 1)
Disclaimer: the generated JS code is not really meant to be read by humans
- DCE will eliminate unused code
- “unused” $\equiv$ “neither exported, nor (indirectly) used by exported code or
main” - code is exported by means of the
@JsExportannotation- to be used on API types and functions
- requires the
kotlin.js.ExperimentalJsExportopt-in
- not all syntactical constructs or types are currently exportable
- members that cannot be exported can be excluded via
@JsExport.Ignore - as a last resort, the warning can be suppressed (as the running example does)
- members that cannot be exported can be excluded via
- “unused” $\equiv$ “neither exported, nor (indirectly) used by exported code or
package my.pkg

import kotlin.js.JsExport

@JsExport
class MyType {
    @JsExport.Ignore // Sequence is not exportable
    val numbers: Sequence<Int> = sequenceOf(1, 2, 3)
}

@JsExport
fun myFunction() { /* ... */ }
// ES modules: packages are flattened
import { MyType, myFunction } from "project-name";

// CommonJS / UMD: packages are preserved
const pkg = require("project-name").my.pkg;
const { MyType, myFunction } = pkg;
Kotlin–JavaScript Mapping (pt. 2)
- Kotlin supports overloading, JS does not
- class / interface member names are mangled to avoid clashes
- the
@JsNameannotation can be used to control the name of a member- to be used on API types and functions
package my.pkg

@JsName("sumNumbers")
fun sum(vararg numbers: Int): Int = numbers.sum()

@JsName("sumIterableOfNumbers")
fun sum(numbers: Iterable<Int>): Int = numbers.sum()

@JsName("sumSequenceOfNumbers")
fun sum(numbers: Sequence<Int>): Int = numbers.sum()
import {
    sumNumbers,
    sumIterableOfNumbers,
    sumSequenceOfNumbers
} from "project-name";
- Kotlin class $\equiv$ JS prototype (with the default ES5 target)
class MyClass(private val argument: String) {
    @JsName("method")
    fun method(): String = argument + "!"
}
function MyClass(argument) {
    this.randomName_1 = argument
}
MyClass.prototype.method = function () {
    return this.randomName_1 + "!"
}
Kotlin–JavaScript Mapping (pt. 3)
- Primitive type mappings are non-trivial (cf. documentation)
-
Kotlin numeric types, except for
kotlin.Long, are mapped to JavaScriptNumber -
kotlin.Charis mapped to a JSNumberrepresenting the character code. -
Kotlin preserves overflow semantics for
kotlin.Int,kotlin.Byte,kotlin.Short,kotlin.Charandkotlin.Long -
kotlin.Longis emulated by a Kotlin class by default- it can be mapped to JS
BigInt(experimental), with thees2020target or the-Xes-long-as-bigintcompiler option
- it can be mapped to JS
-
kotlin.Stringis mapped to JSString -
kotlin.Anyis mapped to JSObject(new Object(),{}, and so on) -
kotlin.Arrayis mapped to JSArray -
Kotlin collections are mapped to
KtList,KtSet,KtMap(and their mutable variants)- which expose JS views via, e.g.,
asJsReadonlyArrayView()
- which expose JS views via, e.g.,
-
kotlin.Throwableis mapped to JSError
-
Kotlin–JavaScript Mapping (pt. 4)
-
practical consequence: no way to distinguish numbers by type
val x: Int = 23 val y: Any = x println(y as Float) // fails on JVM, works on JS -
Kotlin’s
dynamicoverrides the type system, and it is translated “1-to-1”
val string1: String = "some string"
string1.missingMethod() // compilation error

val string2: dynamic = "some string"
string2.missingMethod() // compilation ok, runtime error
- Kotlin’s common std-lib is implemented in JS
- it is bundled into the compiled output (e.g.
kotlin-kotlin-stdlib.mjs), and dead code is eliminated
- it is bundled into the compiled output (e.g.
Kotlin–JavaScript Mapping (pt. 5)
-
Companion objects are treated similarly to Kotlin/JVM
-
Extension methods are treated similarly to Kotlin/JVM
-
Variadic functions are compiled to JS functions accepting an array
- which are not really variadic in JS
fun f(vararg xs: String) { /* ... */ }

// usage:
f("a")
f("a", "b")
f("a", "b", "c")
// usage:
f(["a"])
f(["a", "b"])
f(["a", "b", "c"])
Multi-platform CI/CD
Conceptual workflow (cf. build matrices in the CI lecture):
- Check style (e.g. via KtLint) of all Kotlin sources
- Automatic bug detection (e.g. via Detekt)
- For each operating system
O(e.g. Win, Mac, Linux):- for each target platform
T:- for each relevant version
Vof the platformT(e.g. LTS releases + latest)- ensure main code compiles (e.g. via Gradle task
<T>MainClasses) - ensure test code compiles (e.g. via Gradle task
<T>TestClasses) - ensure test passes (e.g. via Gradle task
<T>Test)
- ensure main code compiles (e.g. via Gradle task
- for each relevant version
- Apple targets require macOS runners
- for each target platform
- If a release is needed (e.g. commit on the default branch)
- for each target platform
T$\cup$kotlin-multiplatform:- assemble compiled code into archive
- push archive on main repository
Rof platformT
- for each target platform
- The running example’s workflows test the JVM and JS targets on 3 OSs $\times$ several JDK / Node versions
About the practical CI/CD
-
Even more complicated, because release on Maven Central is complex
- since June 2025, via the Central Publisher Portal (the legacy OSSRH service has been shut down)
-
Setting up a CI/CD pipeline of this kind requires a lot of work
- and Gradle / GitHub Actions boilerplate
-
Recommendations:
- Use templates, such as
template-kt-mpp-project - Use Gradle plugins, such as
kt-mpporvanniktech/gradle-maven-publish-plugin - Use existing projects as examples, e.g.
2p-kt
- Use templates, such as
Repositories by platform (pt. 1)
Takeaway: each platform has some preferred main repository where users expect to find packages
-
JVM$\rightarrow$ Maven Central Repository (MCR)- other Maven repositories exist, but they are more fragile
-
Kotlin / Multiplatform $\rightarrow$ MCR
-
JS$\rightarrow$ npm registry -
Android$\rightarrow$ libraries: MCR or Google’s Maven repository; apps: Google Play -
Mac/iOS$\rightarrow$ libraries: Swift Package Manager or CocoaPods; apps: App Store- or Homebrew, for command-line tools
Repositories by platform (pt. 2)
-
Windows$\rightarrow$ Microsoft Store- or Chocolatey
- or Scoop
-
Linux$\rightarrow$ depends on the distro- e.g. Arch Linux $\rightarrow$ AUR
- inter-distro: Flatpak $\rightarrow$ Flathub
-
Python$\rightarrow$ PyPI -
.NET$\rightarrow$ NuGet
Multi-platform programming
Write first, wrap elsewhere
Write first, wrap elsewhere: the case of JPype
-
At the end of the day, the Python interpreter is C software
-
Most commonly, efficient Python code is written in C and then wrapped into Python
-
Put simply, the JVM too is C++ software
-
Can Python libraries be written in Java (or Kotlin/JVM) and then wrapped into Python?
-
Apparently yes, via several ad-hoc bridging technologies:
- JPype a bridge for calling JVM code from Python as a native library
- Jython a JVM-based Python interpreter (supporting Python 2.7 only)
- GraalPy a Python 3 implementation on GraalVM, interoperating with Java
- Py4J an RPC based bridge for calling Java from Python
- Pyjnius similar to JPype, but based on Cython
- and many others…
-
Why exactly JPype?
- still maintained, works with vanilla CPython, good documentation, good interoperability with JVM types
JPype overview
-
Ensure you have a JVM installed on your system
- with the
JAVA_HOMEenvironment variable set to the JVM installation directory
- with the
-
Ensure your compiled Java code is available as a
.jarfile- say, in
/path/to/my.jar
- say, in
-
Install the JPype package via
pip install JPype1 -
You first need JPype to start a JVM instance in your Python process
- by default, the JVM location is inferred from the
JAVA_HOMEenvironment variable
import jpype # start the JVM jpype.startJVM(classpath=["/path/to/my.jar"]) - by default, the JVM location is inferred from the
-
Once the JVM is started, one can import Java classes and call their methods as if they were Python objects
import jpype.imports # this is necessary to import Java classes from java.lang import System # import the java.lang.System class System.out.println("Hello World!")jpype.importsworks for well-known top-level domains (e.g.java,javax,com,org)- for other ones (e.g.
io.github.*) usejpype.JClass("...")/jpype.JPackage("..."), orjpype.imports.registerDomain("io")
- for other ones (e.g.
- by default (
convertStrings=False), Java methods return Java strings, to be converted viastr(...)when needed
JPype at runtime
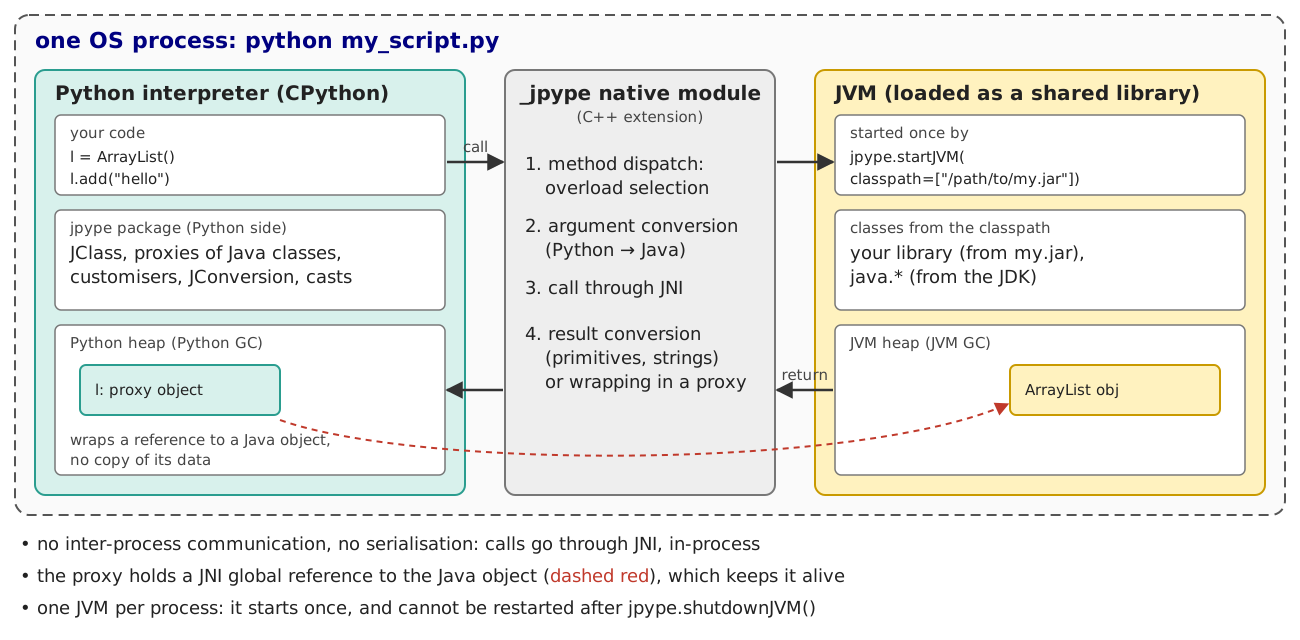
JPype’s Bridging Model (pt. 1)
Overview on the official documentation
-
Java classes are presented as similarly to Python classes as possible
-
the only major difference is that Java classes and objects are closed and cannot be modified
- except via customisers (see later)
| Description | Java | Python |
|---|---|---|
| Import a class | import org.pkg.MyClass |
from org.pkg import MyClass |
| Import a class without a well-known TLD | import zippy.NonStandard |
NonStandard = JClass('zippy.NonStandard') |
| Construct an object | MyClass o = new MyClass(1); |
o = MyClass(1) |
| Get / set a static field | MyClass.staticField = 2; |
MyClass.staticField = 2 |
| Call a static / member method | MyClass.callStatic(1); o.callMember(1); |
MyClass.callStatic(1); o.callMember(1) |
| Member with Python naming conflict | o.pass() |
o.pass_() |
| Check inheritance | o instanceof MyClass |
isinstance(o, MyClass) |
| Cast to a specific type | (BaseClass) o |
BaseClass @ o |
JPype’s Bridging Model (pt. 2)
Overview on the official documentation
-
Java exceptions extend from Python exceptions
-
Java exceptions can be dealt with in the same way as Python native exceptions
- i.e. via
try-exceptblocks
- i.e. via
-
JExceptionserves as the base class for all Java exceptions
| Description | Java | Python |
|---|---|---|
| Catch an exception | try { o.throwsException(); } catch (java.lang.Exception ex) { ... } |
try: o.throwsException()except java.lang.Exception as ex: ... |
| Throw an exception to Java | throw new java.lang.Exception("Problem"); |
raise java.lang.Exception("Problem") |
| Check if an object is a Java exception | isinstance(obj, JException) |
|
| Closeable items | try (InputStream is = Files.newInputStream(file)) { ... } |
with Files.newInputStream(file) as is: ... |
JPype’s Bridging Model (pt. 3)
Overview on the official documentation
-
most Python primitives directly map into Java primitives
-
however, Python does not have the same primitive types…
-
… hence, explicit casts may be needed in some cases
-
each primitive Java type is exposed in JPype (
jpype.JBoolean,.JByte,.JChar,.JShort,.JInt,.JLong,.JFloat,.JDouble).
| Description | Java | Python |
|---|---|---|
| Cast to hit an overload | o.call((int) v); |
o.call(JInt(v)) |
| Create a primitive array | int[] array = new int[5]; |
array = JInt[5] |
| Create a rectangular primitive array | int[][] array = new int[5][10]; |
array = JInt[5, 10] |
| Create an array of arrays | int[][] array = new int[5][]; |
array = JInt[5, :] |
| Create an initialised primitive array | int[] array = new int[]{1, 2, 3}; |
array = JInt[:]([1, 2, 3]) |
| Create an initialised boxed array | Integer[] array = new Integer[]{1, 2, 3}; |
array = java.lang.Integer[:]([1, 2, 3]) |
| Put a specific primitive type on a list | List<Integer> l = new ArrayList<>();l.add(1); |
l = ArrayList()l.add(JInt(1)) |
| Box a primitive | Integer boxed = 1; |
boxed = JObject(JInt(1)) |
JPype’s Bridging Model (pt. 4)
Overview on the official documentation
-
Java strings are similar to Python strings
-
they are both immutable and produce a new string when altered
-
most operations can use Java strings in place of Python strings
- with minor exceptions, as Python strings are not completely duck typed
-
when comparing or using strings as dictionary keys, all
JStringobjects should be converted to Python
| Description | Java | Python |
|---|---|---|
| Create a Java string | String s = new String("foo"); |
s = JString("foo") |
| Create a Java string from bytes | byte[] b;String s = new String(b, "UTF-8"); |
b = b'foo's = JString(b, "UTF-8") |
| Convert a Java string | str(javaStr) |
|
| Compare Python and Java strings | str(javaStr) == pyString |
|
| Compare Java strings | javaStr.equals("foo") |
javaStr == "foo" |
| Check if an object is a Java string | isinstance(obj, JString) |
JPype’s Bridging Model (pt. 5)
Overview on the official documentation
-
Java arrays are mapped to Python lists
-
more precisely, they operate like Python lists, but they are fixed in size
-
reading a slice from a Java array returns a view of the array, not a copy
-
passing a slice of a Python list to Java will create a copy of the sub-list
| Description | Java | Python |
|---|---|---|
| Create a single-dimension array | MyClass[] array = new MyClass[5]; |
array = MyClass[5] |
| Create a multi-dimension array | MyClass[][] array2 = new MyClass[5][]; |
array2 = MyClass[5, :] |
| Access an element | array[0] = new MyClass(); |
array[0] = MyClass() |
| Size of an array | array.length |
len(array) |
| Get last element | MyClass a = array[array.length - 1]; |
a = array[-1] |
| Slice an array | a = array[2:5] |
|
| Clone an array | MyClass[] a = array.clone(); |
a = array.clone() |
| Convert to Python list | pylist = list(array) |
|
| Iterate elements | for (MyClass element : array) { ... } |
for element in array: ... |
| Check if an object is a Java array | isinstance(obj, JArray) |
JPype’s Bridging Model (pt. 6)
Overview on the official documentation
-
Java collections are overloaded with Python syntax where possible
- to operate similarly to Python collections
-
Java’s
Iterables are mapped to Python iterables by overriding the__iter__method -
Java’s
Collections are mapped to Python containers by overriding__len__ -
Java’s
Maps support Python’s dictionary syntax by overriding__getitem__and__setitem__ -
Java’s
Lists support Python’s list syntax by overriding__getitem__and__setitem__
| Description | Java | Python |
|---|---|---|
| Import list type | import java.util.ArrayList; |
from java.util import ArrayList |
| Construct a list | List<Integer> l = new ArrayList<>(); |
l = ArrayList() |
| Get length of list | int sz = l.size(); |
sz = len(l) |
| Get list item | Integer i = l.get(0); |
i = l[0] |
| Set list item | l.set(0, 1); |
l[0] = JInt(1) |
| Iterate list elements | for (Integer e : l) { ... } |
for e in l: ... |
| Import map type | import java.util.HashMap; |
from java.util import HashMap |
| Construct a map | Map<String, Integer> m = new HashMap<>(); |
m = HashMap() |
| Get length of map | int sz = m.size(); |
sz = len(m) |
| Get map item | Integer i = m.get("foo"); |
i = m["foo"] |
| Set map item | m.put("foo", 1); |
m["foo"] = JInt(1) |
| Iterate map entries | for (Map.Entry<String, Integer> e : m.entrySet()) { ... } |
for e in m.entrySet(): ... |
JPype’s Bridging Model (pt. 7)
Overview on the official documentation
-
Java interfaces can be implemented in Python, via JPype’s
@JImplementsand@JOverridedecorators -
No Java class (not even abstract ones) can be extended in Python
-
Python lambda expressions can be cast to Java’s functional interfaces
| Description | Java | Python |
|---|---|---|
| Implement an interface | public class PyImpl implements MyInterface { |
@JImplements(MyInterface) |
| Extend a class | public class PyImpl extends MyClass { ... } |
not supported |
| Lambdas | DoubleUnaryOperator u = (p -> p * 2); |
u = DoubleUnaryOperator @ (lambda x: x * 2) |
| Add methods to an existing Java class | @JImplementationFor("java.util.Map") |
JPype type conversion model
Overview on the official documentation
| Python \ Java | byte |
short |
int |
long |
float |
double |
boolean |
char |
String |
Array | Object | j.l.Object |
j.l.Class |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
int |
I1 | I1 | X | I | I3 | I3 | X8 | I11 | |||||
float |
I1 | X | I11 | ||||||||||
str |
I2 | X | I | ||||||||||
JByte |
X | I9 | |||||||||||
JShort |
X | I9 | |||||||||||
JInt |
X | I9 | |||||||||||
JLong |
X | I9 | |||||||||||
JFloat |
X | I9 | |||||||||||
JDouble |
X | I9 | |||||||||||
JBoolean |
X | I9 | |||||||||||
JChar |
X | I9 | |||||||||||
JString |
X | I | |||||||||||
JArray |
I/X4 | I | |||||||||||
JObject |
I/X6 | I/X7 | I/X7 | ||||||||||
JClass |
I | X | |||||||||||
| boxed10 | I | I | I | I | I | I | I | I |
Legend (j.l = java.lang):
- empty: there is no way to convert
- explicit (E): only via casting
- implicit (I): JPype will convert as needed
- exact (X): like implicit, but takes priority in overload selection
Notes:
- 1 only if the value fits the Java type
- 2 only strings of length 1
- 3 may be lossy, as in Java
- 4 dimensions and types must match
- 6 only for compatible array classes
- 7 exact for the object’s own class, implicit otherwise
- 8 only
TrueandFalse - 9 boxed as per Java rules
- 10 Java boxed types: always implicit, to disambiguate from primitives
- 11 boxed to
java.lang.Number
Overload selection
-
Consider the following example of Python code with JPype:
import jpype.imports from java.lang import System System.out.println(1) System.out.println(2.0) System.out.println('A') -
Which overload of
System.out.printlnis called among the many admissible ones?- Python’s
2.0is convertible to Java’sfloatanddouble- but Java’s
doubleis the exact match
- but Java’s
- Python’s
'A'is convertible to Java’sStringandchar- but Java’s
Stringis the exact match
- but Java’s
- Python’s
1is implicitly convertible to many types (e.g.int,long,char,boolean,Object)- as of JPype 1.7, this call raises
TypeError: Ambiguous overloads found for java.io.PrintStream.println(int) - an explicit cast solves the issue:
System.out.println(jpype.JInt(1))
- as of JPype 1.7, this call raises
- Python’s
Ambiguous overload selection
-
Consider the following example of Python code with JPype:
import jpype csv = jpype.JClass("io.github.gciatto.csv.Csv") csv.headerOf(["field", "another field"]) -
This would raise the following error:
TypeError: Ambiguous overloads found for io.github.gciatto.csv.Csv.headerOf(list) between: public static final io.github.gciatto.csv.Header io.github.gciatto.csv.Csv.headerOf(java.lang.Iterable) public static final io.github.gciatto.csv.Header io.github.gciatto.csv.Csv.headerOf(java.lang.String[])- because Python’s
listis convertible to both Java’sIterableandString[]- but neither is the exact match
- because Python’s
-
To solve this issue, one can explicitly cast the Python
listto the desired Java type:import jpype import jpype.imports from java.lang import Iterable as JIterable csv = jpype.JClass("io.github.gciatto.csv.Csv") csv.headerOf(JIterable@["field", "another field"]) # returns Header("field", "another field")
Overload selection in a nutshell
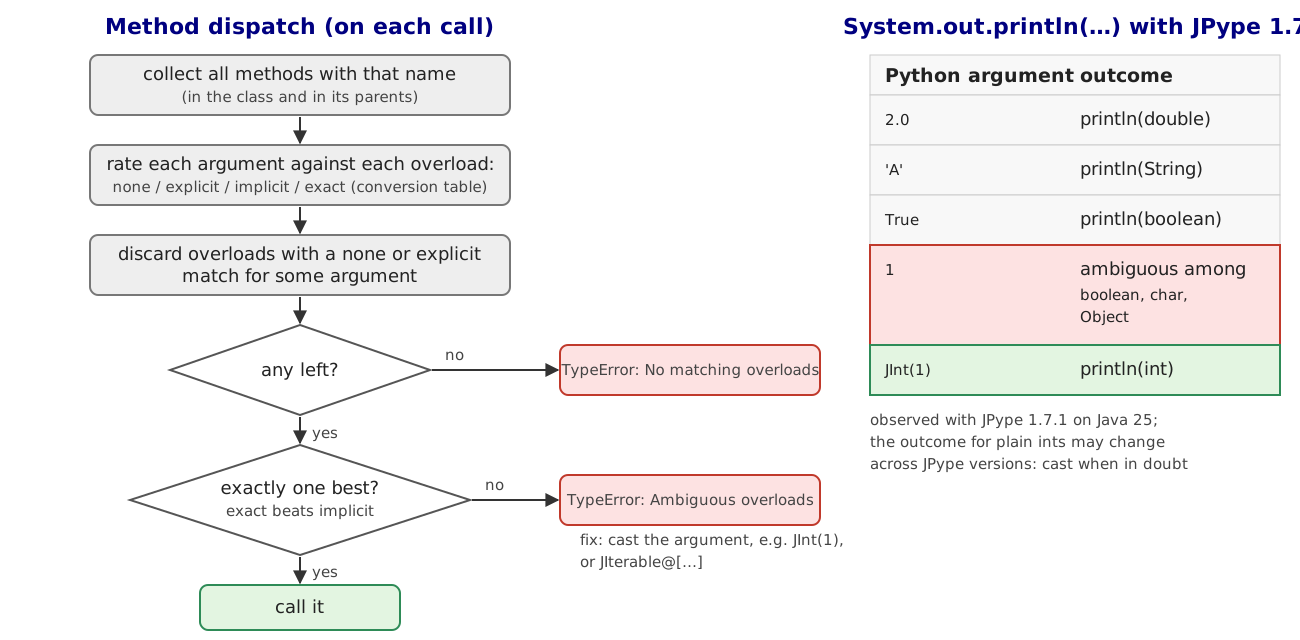
Customising Java types in Python (pt. 1)
-
One may customise the behaviour of Java types in Python by providing custom implementations for them
- by means of the
@JImplementationFordecorator
- by means of the
-
In that case the special method
__jclass_init__is called on the custom implementation, just once, to configure the class -
In type hierarchies, implementations provided for superclasses are inherited by subclasses
Customising Java types in Python (pt. 2)
Consider for instance the following customisations, allowing Java collections to be used with Python syntax
from collections.abc import Sequence


@jpype.JImplementationFor("java.lang.Iterable")
class _JIterable:
    def __iter__(self):
        return self.iterator()  # supports "for x in coll" syntax


@jpype.JImplementationFor("java.util.Collection")
class _JCollection:
    def __len__(self):
        return self.size()       # supports "len(coll)" syntax

    def __contains__(self, i):
        return self.contains(i)  # supports "i in coll" syntax

    # __iter__ is inherited from _JIterable
    # because in Java: Collection extends Iterable
@jpype.JImplementationFor("java.util.List")
class _JList:
    def __jclass_init__(self):
        # makes isinstance(x, Sequence) true for Java lists
        Sequence.register(self)

    def __getitem__(self, ndx):
        return self.get(ndx)   # supports "list[i]" syntax

    def append(self, obj):
        return self.add(obj)   # supports "list.append(obj)" syntax

    # __len__, __contains__, __iter__ are inherited
    # from _JCollection
simplified from JPype’s codebase
Making wrapped code Pythonic (pt. 1)
-
The code wrapped via JPype is not Pythonic by default
- it works in principle, but it is very hard to use for the average Python developer
- we cannot assume the average Python developer is familiar with Java…
- nor with JPype
- and the developer should know both aspects to use the wrapped code as is
- it works in principle, but it is very hard to use for the average Python developer
-
It is important to make the wrapped code as Pythonic as possible
- factory methods for building instances of types
- simplified package structure
- e.g.
io.github.gciatto.csv.Csv$\rightarrow$jcsv.Csv
- e.g.
- properties instead of getters and setters
snake_caseinstead ofcamelCase- magic methods implemented whenever possible
- e.g.
__len__forjava.util.Collection - e.g.
__getitem__forjava.util.List
- e.g.
- optional parameters in methods instead of overloads
-
All such refinements can be done in JPype via customisations of the Java types
- unit tests should be written to ensure the customisations are not broken by future changes
Making wrapped code Pythonic (pt. 2)
Workflow
For all public types in the wrapped Java library:
- decide their corresponding Python package
- provide Pythonic factory methods
- customise the Python class to make it Pythonic (possibly exploiting type hierarchies to save time)
- add properties calling getters/setters
- override Java methods to make them Pythonic
- e.g. use magic methods where possible
- e.g. use optional parameters where possible, removing the need for overloads
- write unit tests for Pythonic API
Example: the jcsv package (pt. 1)
-
The
jcsvpackage (modulecsv-python) is a Pythonic wrapper for our JVM-basedio.github.gciatto.csvlibrary -
Java’s type definitions are brought to Python in jcsv/init.py:
import typing

import jpype

from jcsv import (
    jvm,  # starts the JVM, with csv.jar on the classpath
    python,
)

_csv = jpype.JPackage("io.github.gciatto.csv")
_java = jpype.JPackage("java.lang")


Table = _csv.Table
Row = _csv.Row
Record = _csv.Record
Header = _csv.Header
Formatter = _csv.Formatter
Parser = _csv.Parser
Configuration = _csv.Configuration
Csv = _csv.Csv
CsvJvm = _csv.CsvJvm- importing
jcsv.jvmstarts the JVM (see later), hence it must come before any access to Java types CsvandCsvJvmare the Java classes generated fromCsv.ktandCsv.jvm.kt, thanks to@file:JvmName- this makes it possible to write
from jcsv import Table, Record, Headeron the user side
Example: the jcsv package (pt. 2)
Parsing and formatting operations are mapped straightforwardly to Python functions (with optional parameters replacing Kotlin’s default arguments):
def parse_csv_string(
    string,
    separator=Csv.DEFAULT_SEPARATOR,
    delimiter=Csv.DEFAULT_DELIMITER,
    comment=Csv.DEFAULT_COMMENT,
):
    return Csv.parseAsCSV(string, separator, delimiter, comment)


def parse_csv_file(
    path,
    separator=Csv.DEFAULT_SEPARATOR,
    delimiter=Csv.DEFAULT_DELIMITER,
    comment=Csv.DEFAULT_COMMENT,
):
    return CsvJvm.parseCsvFile(str(path), separator, delimiter, comment)


def format_as_csv(
    rows,
    separator=Csv.DEFAULT_SEPARATOR,
    delimiter=Csv.DEFAULT_DELIMITER,
    comment=Csv.DEFAULT_COMMENT,
):
    return Csv.formatAsCSV(jvm.Iterable @ rows, separator, delimiter, comment)
Example: the jcsv package (pt. 3)
Ad-hoc factory method for building Header instances:
def header(*args):
    if len(args) == 1 and isinstance(args[0], int):
        return Csv.anonymousHeader(args[0])
    return python.iterable_or_varargs(args, lambda xs: Csv.headerOf(jvm.Iterable @ map(str, xs)))
making it possible to write the following code on the user side:
import jcsv

header1 = jcsv.header("column1", "column2", "column3")
header2 = jcsv.header(3) # anonymous header with 3 columns
columns = (f"column{i}" for i in range(1, 4)) # generator
header3 = jcsv.header(columns) # same as header1
Function iterable_or_varargs (in jcsv/python.py) simulates multiple overloads:
def iterable_or_varargs(
    args: tuple,
    dispatch: Callable[[Iterable[T]], R] = lambda x: x,
    atomic: tuple = (str, bytes),
) -> R:
    """
    Simulates the overloads f(*items) and f(iterable_of_items):
    a single iterable argument is unpacked, unless it is an instance of one of the `atomic` types.
    """
    if len(args) == 1:
        item = args[0]
        if isinstance(item, Iterable) and not isinstance(item, atomic):
            return dispatch(item)
        return dispatch([item])
return dispatch(args)- strings are iterable too, but
header("col")must not split"col"into characters
Example: the jcsv package (pt. 4)
-
How can
jvm.Iterable @ map(str, xs)work, if Python’smapis not convertible to Java’sIterable? -
A custom conversion is registered in jcsv/jvm/__jvmutils.py, via the
@JConversiondecorator:
def jiterable(iterable: PyIterable) -> Iterable:
    assert isinstance(iterable, PyIterable)
    return _IterableAdapter(iterable)


@jpype.JConversion("java.lang.Iterable", instanceof=PyIterable, excludes=str)
def _java_iterable_convert(jcls, obj):
return jiterable(obj)- where
_IterableAdapteris a Python class implementing Java’sIterableinterface:
@jpype.JImplements("java.lang.Iterable", deferred=True)
class _IterableAdapter:
    def __init__(self, iterable):
        assert isinstance(iterable, PyIterable)
        self._iterable = iterable

    @jpype.JOverride
    def iterator(self):
return _IteratorAdapter(iter(self._iterable))_IteratorAdaptersimilarly implementsjava.util.Iteratoron top of Python iterators
Example: the jcsv package (pt. 5)
Ad-hoc factory methods for building Record and Table instances:
def record(header, *args):
    return python.iterable_or_varargs(
        args, lambda xs: Csv.recordOf(header, jvm.Iterable @ map(str, xs))
    )


def __ensure_header(h):
    return h if isinstance(h, Header) else header(h)


def __ensure_record(r, h):
    return r if isinstance(r, Record) else record(h, r)


def table(header, *args):
    header = __ensure_header(header)
    return python.iterable_or_varargs(
        args,
        lambda rows: Csv.tableOf(header, jvm.Iterable @ [__ensure_record(r, header) for r in rows]),
        atomic=(str, bytes, Row),  # a single Row is a record, not an iterable of records
)tableaccepts headers and records either as Java objects or as Python iterables, e.g.:jcsv.table(["a", "b"], [1, 2], [3, 4])
Example: the jcsv package (pt. 6)
The Row class is customised to make it more Pythonic:
@jpype.JImplementationFor("io.github.gciatto.csv.Row")
class _Row:
    def __len__(self) -> int:
        return self.getSize()

    def __getitem__(self, item: int | str) -> str:
        if isinstance(item, int) and item < 0:
            item = len(self) + item
        try:
            return self.get(item)
        except _java.IndexOutOfBoundsException as e:
            raise IndexError(f"index {item} out of range") from e

    @property
    def size(self) -> int:
return len(self)- supporting the syntax
len(row)instead ofrow.getSize() - supporting the syntax
row[i]instead ofrow.get(i) - supporting the syntax
row[-i]instead ofrow.get(row.getSize() - i) - letting
IndexErrorbe raised instead ofIndexOutOfBoundsException - supporting the syntax
row.sizeinstead ofrow.getSize()
Example: the jcsv package (pt. 7)
Header inherits all customisations of Row (since Header extends Row), plus the following ones:
@jpype.JImplementationFor("io.github.gciatto.csv.Header")
class _Header:
    @property
    def columns(self) -> list[str]:
        return [str(c) for c in self.getColumns()]

    def __contains__(self, item: str) -> bool:
        return self.contains(item)

    def index_of(self, column: str) -> int:
return self.indexOf(column)- supporting the syntax
header.columnsinstead ofheader.getColumns() - supporting the syntax
column in headerinstead ofheader.contains(column) - supporting the syntax
header.index_of(column)instead ofheader.indexOf(column)
Example: the jcsv package (pt. 8)
Record inherits all customisations of Row (since Record extends Row), plus the following ones:
@jpype.JImplementationFor("io.github.gciatto.csv.Record")
class _Record:
    @property
    def header(self) -> Header:
        return self.getHeader()

    @property
    def values(self) -> list[str]:
        return [str(v) for v in self.getValues()]

    def __contains__(self, item: str) -> bool:
return self.contains(item)- supporting the syntax
record.headerinstead ofrecord.getHeader() - supporting the syntax
record.valuesinstead ofrecord.getValues() - supporting the syntax
value in recordinstead ofrecord.contains(value)
Example: the jcsv package (pt. 9)
The Table class is customised too, to make it more Pythonic:
@jpype.JImplementationFor("io.github.gciatto.csv.Table")
class _Table:
    @property
    def header(self) -> Header:
        return self.getHeader()

    def __len__(self) -> int:
        return self.getSize()

    def __getitem__(self, item: int) -> Row:
        if isinstance(item, int) and item < 0:
            item = len(self) + item
        try:
            return self.get(item)
        except _java.IndexOutOfBoundsException as e:
            raise IndexError(f"index {item} out of range") from e

    @property
    def records(self) -> list[Record]:
        return self.getRecords()

    @property
    def size(self) -> int:
return len(self)- supporting the syntax
table.headerinstead oftable.getHeader() - supporting the syntax
len(table)instead oftable.getSize() - supporting the syntax
table[i]instead oftable.get(i) - supporting the syntax
table[-i]instead oftable.get(table.getSize() - i) - supporting the syntax
table.recordsinstead oftable.getRecords()
Including .jars in JPype projects (pt. 1)
csv-python/
├── build.gradle.kts            # Gradle build: generation of csv.jar + Python tasks
├── pyproject.toml              # Python project description (generated from Gradle, tracked)
├── uv.lock                     # pinned versions of Python dependencies
├── .python-version             # Python version used for development
├── jcsv/
│   ├── __init__.py
│   ├── __main__.py             # CLI, installed as the `jcsv` command
│   ├── jvm/
│   │   ├── __init__.py         # this is where the JVM is started via JPype
│   │   ├── __jvmutils.py       # Java <-> Python conversions
│   │   └── csv.jar             # the fat JAR of the JVM-based library (generated, not tracked)
│   └── python.py
└── tests/
    ├── __init__.py
    ├── test_parsing.py
    └── test_python_api.py
-
We need to ensure that the JVM-based library is available on the system where
jcsvis installed- why not include it in the Python package?
-
The
build.gradle.ktsfile automates the generation of thecsv.jarfile- it is a fat JAR containing all the dependencies of the JVM-based library
- such JAR is placed in the
jcsv/jvmdirectory, i.e. inside the Python package - so it is included in the wheel built by
uv build, and distributed with the Python library
-
The
jcsv/jvm/__init__.pyfile starts the JVM, withcsv.jaron the class path
Including .jars in JPype projects (pt. 2)
The build.gradle.kts of csv-python relies on the gradle-python-uv plugin, mapping Gradle’s lifecycle tasks (test, check, assemble, …) onto uv commands:
plugins {
    id("io.github.gciatto.python-uv")
}

python {
    pyproject {
        name = "jcsv"
        description = "Pythonic wrapper of a Kotlin/JVM CSV library, via JPype"
        dependency("JPype1>=1.7.1")
        dependency("jdk4py>=25.0.2.1")
        // no mypy: JPype customisers call Java methods that only exist at runtime
        poeSequence("static-checks", "compile", "format-check", "ruff-check")
    }
}

// Copies the fat JAR of :csv-core into the Python package, as jcsv/jvm/csv.jar
val createCoreJar by tasks.registering(Copy::class) {
    group = "Python"
    val shadowJar by project(":csv-core").tasks.getting(Jar::class)
    dependsOn(shadowJar)
    from(shadowJar.archiveFile) {
        rename(".*?\\.jar", "csv.jar")
    }
    into(projectDir.resolve("jcsv/jvm"))
}

// tests, static checks, and packaging (uv build) all need csv.jar
tasks.withType<PoeTask>().configureEach { dependsOn(createCoreJar) }
tasks.named("uvBuild") { dependsOn(createCoreJar) }pyproject.tomlis generated from thepython { pyproject { ... } }block (./gradlew generatePyproject)createCoreJarcopies the fat JAR ofcsv-core(created by the Shadow plugin) into the Python package
Including the JVM in JPype projects
-
We need to ensure that some JVM is available on the system where
jcsvis installed -
Notice that the JVM is available as a Python dependency too: jdk4py
- a minimal JDK runtime, shipped as platform-specific wheels (Linux, macOS, Windows; x86_64 and arm64)
-
So, the JVM can be automatically downloaded and installed as a dependency of
jcsv(seedependency("jdk4py>=25.0.2.1")in the build file) -
Then, one may simply configure JPype to use that JVM, in jcsv/jvm/init.py:
import sys
from pathlib import Path

import jpype
from jdk4py import JAVA_HOME

# the directory where csv.jar is placed
CLASSPATH = Path(__file__).parent

# the list of all .jar files in CLASSPATH
JARS = [str(j.resolve()) for j in CLASSPATH.glob("*.jar")]

# the JVM library shipped by jdk4py, for the current OS
JVM_LIB = {"win32": "jvm.dll", "darwin": "libjli.dylib"}.get(sys.platform, "libjvm.so")
JVM_PATH = str(next(JAVA_HOME.rglob(JVM_LIB)))

jpype.startJVM(jvmpath=JVM_PATH, classpath=JARS)- Try it:
./gradlew :csv-python:assemble, thenpip install csv-python/build/python/dist/*.whlin a clean virtual environment
About unit testing
-
Unit tests are essential to ensure the correctness of the Pythonic API
- they prevent corruption of the Pythonic API when the JAR is updated
-
It is important to test all the customisations and factory methods
- because these are not covered by the unit tests of the JVM-based library
-
Consider for instance tests in tests/test_parsing.py and tests/test_python_api.py, e.g.:
class TestFactories(unittest.TestCase):
    def test_single_string_column(self):
        self.assertEqual(jcsv.header("col").columns, ["col"])

    def test_iterable_of_columns(self):
        self.assertEqual(jcsv.header(f"c{i}" for i in range(3)).columns, ["c0", "c1", "c2"])

    def test_single_record_table(self):
        h = jcsv.header("a", "b")
        t = jcsv.table(h, jcsv.record(h, "1", "2"))
        self.assertEqual(len(t), 2)
self.assertEqual(t[1].values, ["1", "2"])- Run them via
./gradlew :csv-python:test(i.e.uv run poe test, i.e.pytest)- they depend on
createCoreJar, so the JAR is always up to date
- they depend on
Example: the jcsv package (recap)
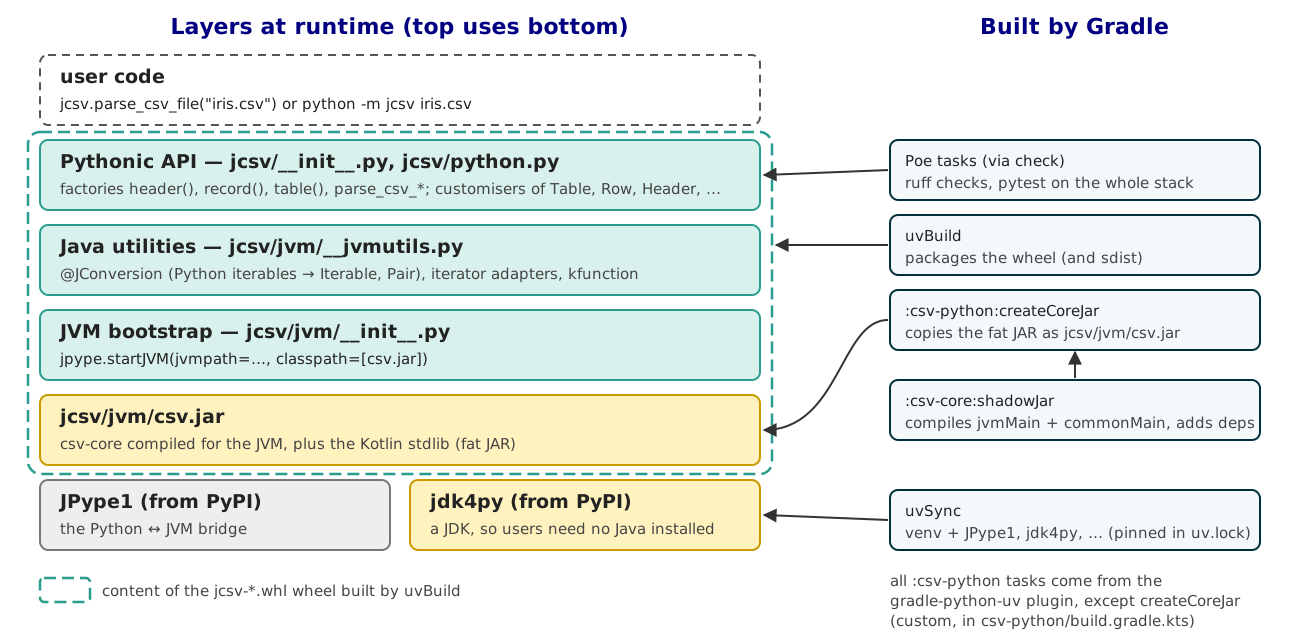
Wrap-up
| Write once, build anywhere (e.g. Kotlin MP) | Write first, wrap elsewhere (e.g. JPype) | |
|---|---|---|
| Code base | one, in a “super-language”, plus platform-specific parts | one main implementation, plus one wrapper per platform |
Effort vs. N platforms |
common code written once, platform-specific code N times |
API / wrapper code (and its tests) written N times |
| Runtime | native runtime of each platform | the main platform’s runtime is shipped along (e.g. JVM inside a Python wheel) |
| Idiomatic API | partially (e.g. @JvmName, @JsExport, @JsName) |
fully customisable in each wrapper |
| Limitations | small common std-lib, platform-specific build/release tooling | bridging overhead, type-conversion ambiguities, larger packages |
Both approaches require clear separation between API and implementation, and tests on every platform
Lecture is Over
Compiled on: 2026-11-06 — printable version